System design interview guide
Job Scheduler System Design
Picture a company that runs small background chores for its customers, such as sending emails, checking payments and building reports. Each chore is called a job, and the part of the system that decides when each job starts and which machine runs it is called a job scheduler. At midnight, 50,000 jobs become due in the same second, and most of them are marketing emails. One of them is a payment check that has to finish on time, but the email batch was taken first, so the payment check waits behind it. If a machine dies halfway through a job, the scheduler must also run that job again without charging a customer twice, so a good answer explains when jobs start, who runs them, and how a retry stays safe.
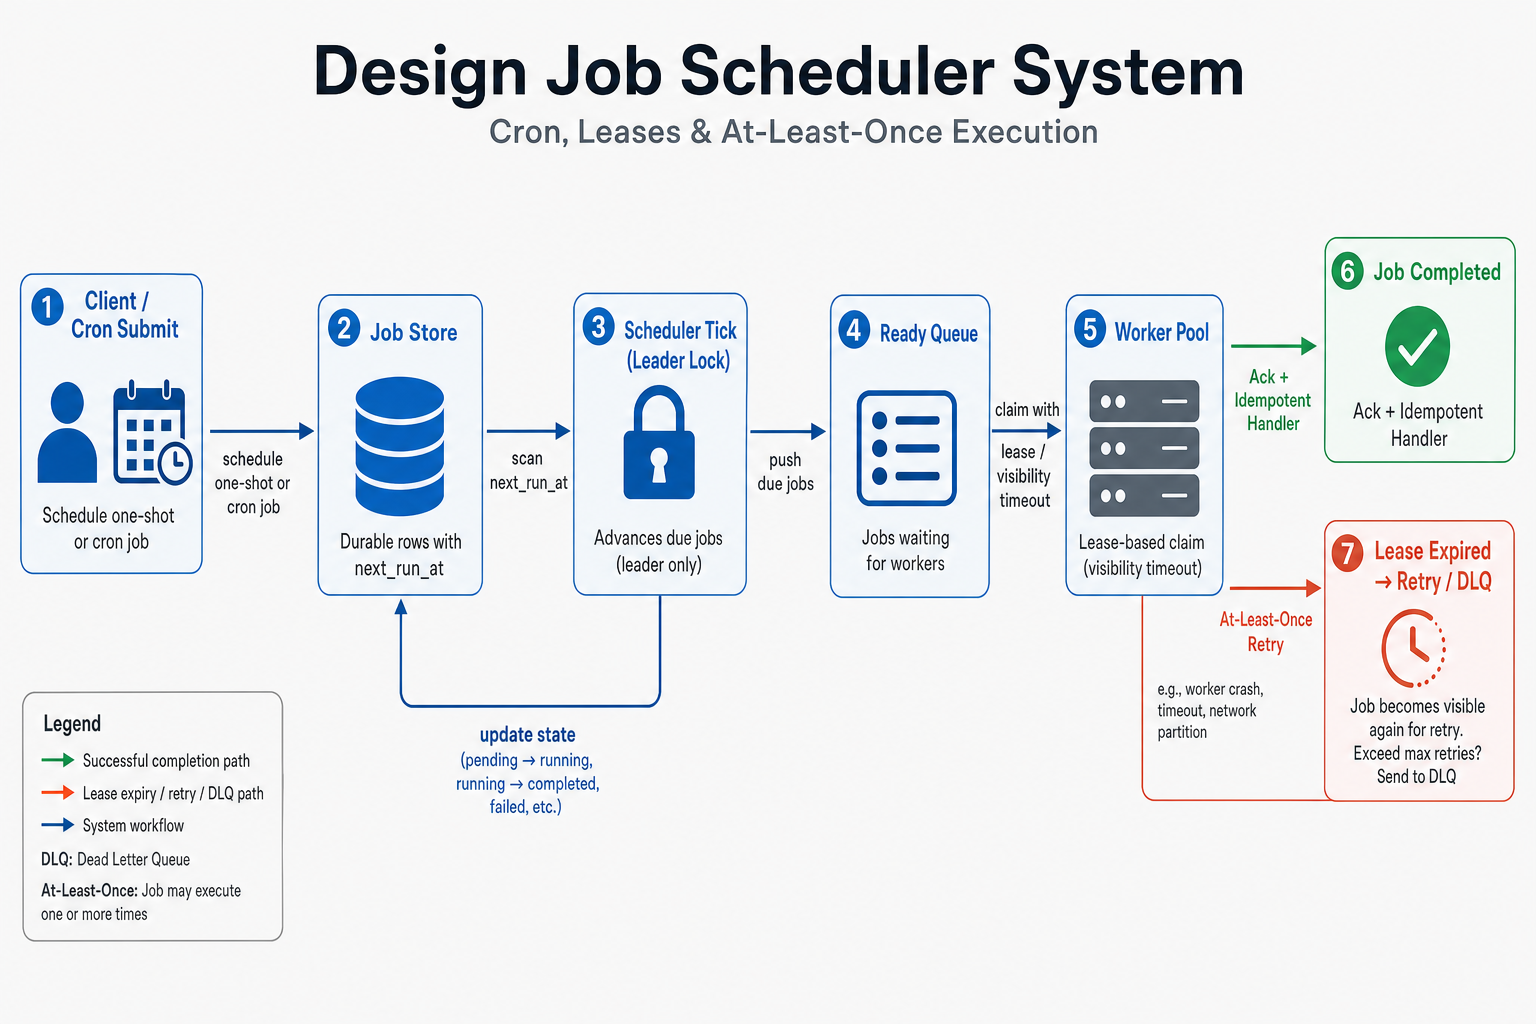
Problem statement
Design the system that starts background work at the right time and hands each piece of work to a machine that runs it. People call each piece of work a job, and they call the system a job scheduler. It must accept work that runs once and work that repeats on a schedule, decide which jobs go first when many are waiting, try again when a run fails, and give each running job a timed claim (a lease) so a dead machine cannot leave work stuck forever. It must also avoid starting the same midnight run twice when the machine that keeps the clock is replaced. Interviewers grade whether you separate “when to run” from “who runs it safely,” and whether the job’s own code survives being delivered more than once.
Introduction
The problem: a midnight batch and a payment check
Picture a company that runs a lot of small chores in the background for its customers. Some chores send emails, some check whether a payment went through, and some build nightly reports. Each chore is called a job. Nobody sits and watches them happen. A person or another system says “run this at midnight” or “run this every hour”, and the company expects it to happen on time without anyone pressing a button.
Now imagine what midnight looks like. A marketing team has scheduled a huge email campaign, and 50,000 jobs become due in the same second. The billing team has also scheduled one payment check for the same moment, and that check has to finish on time because money is waiting on it. If the system simply hands out jobs in the order they arrived, the payment check ends up at the back of a very long line behind the emails.
It gets worse in two quieter ways. A machine that was running a job can crash halfway through, and nobody knows whether the customer was already charged. And the machine that keeps track of the clock can itself be replaced in the middle of the night, so the new one does not know that the first one already started the midnight batch, and everything runs twice. People feel these failures as duplicate charges, emails that arrive ten times, or work that quietly never happens.
The part of the system that answers “what should start now, and who should run it?” is called a job scheduler. It looks like a small thing, which is exactly why interviewers like it. Describing the happy path takes a minute, and the real version is full of choices. This page walks through those choices in the order you would actually make them: first what we are solving and why, then what the system must do, then how big it is, and only after that the design itself.
Why teams bother with a job scheduler
You have probably used products that depend on a scheduler without knowing it. A subscription renews every month, a weekly summary email lands on Monday morning, a nightly backup runs while everyone sleeps, and a payment that failed is tried again a day later. Behind each of those is a reason a company cannot just let people or servers do it by hand.
Work that must happen later. Many things should not happen while the customer waits. Charging a card on the first of the month or sending a reminder two days before an appointment are promises about a future time, and something has to remember them reliably.
Work that is too slow for a web request. Building a large report can take ten minutes. A web page cannot wait that long, so the work is handed to a background machine and the page answers right away.
Protecting everyone else. If one team can start a million jobs at once and use every machine, every other team waits. A shared scheduler lets the company decide whose work goes first and how much of the capacity each team may use.
Surviving failures. Machines crash, networks drop, and other companies’ servers have bad afternoons. A job that fails because of a short problem should be tried again a few times, and a job that keeps failing should be set aside for a person, instead of disappearing or looping forever.
One place to answer questions. “Did the report run last night?” and “Why is this payment still waiting?” are support questions that need one trustworthy record, not a search through the logs of fifty servers.
What problem are we solving?
A client says: “Run this work at time T”, or “run this every night at midnight”. The system must remember that promise even if machines restart, notice when the time arrives, make sure a machine does the work, and tell the client what happened. Success looks like this: every promised job runs when it is due or shortly after, a failed job is tried again a sensible number of times, and no customer is charged twice because the system hiccupped.
There are three ways this can go wrong, and they are what the interviewer is listening for. A job can run twice, which is how duplicate charges and repeated emails happen. A job can be lost, which means a promise nobody keeps. Or a job can be stuck in a “running” state because the machine that owned it died, so nothing else ever picks it up.
We will not guess at the design yet. First we need to be clear about what the system must do, and how well, so that each choice later has a reason behind it.
This page is the interview deep dive in the system design interview guides hub. If you want to practice the requirements stage before reading on, there is a practice link in the requirements section below.
How to approach
In an interview you do not start by drawing boxes. You start by turning a short, vague prompt into a clear contract: what kinds of jobs there are, what the system must do, how well it must do it, and what is out of scope. Only then do you size the problem, make the design decisions one at a time, and draw the result. The list below is the order this page follows.
How to design a job scheduler in an interview
- Clarify the problem: whether jobs run once or repeat, how long they take, how strong a promise the product needs about running them, whether the caller waits for the result, and how big the system is.
- Write the functional requirements (what the system does) and the non-functional requirements (how reliable, how fast, how big).
- Estimate the size: how many jobs, how many workers, how large the burst at the top of the hour is, and how fast the history grows.
- Make the design decisions in order: where the promise to run a job is stored, how the system notices a job is due, how due jobs reach workers, how a worker takes ownership of one, what happens on failure, how a retry stays safe, how repeating schedules fire once, and who goes first.
- Draw the picture those decisions produce, then walk one job through it from “submitted” to “finished”.
- Go deeper where the interviewer pushes: the worker that dies mid-job, the scheduler that fails over at midnight, the crowd at the top of the hour, and one production failure.
Clarifying questions (say these in the room)
In a real interview the prompt is only a few words: “Design a job scheduler.” Before you design anything, ask questions until the problem is clear. Each answer below changes the design, which is why it is worth asking.
You: “Are the jobs one-off, repeating on a schedule like cron, or chains where one job waits for another? If you want full workflow graphs, I would park that and focus on storing, starting and retrying jobs.”
Interviewer: “Mostly one-off and repeating. Mention dependencies briefly if you have time.”
That answer sets the minimum product: a scheduler that stores jobs, starts them and retries them, not a full workflow engine. Cron is the name for a schedule written as a pattern such as “at minute 0 of every hour”, and it will matter because many jobs share the same pattern.
You: “What promise does the product need about running each job? I assume we are allowed to try a job more than once if something fails, so a payment job has to be safe if it happens to run twice.”
Interviewer: “Yes, retries are expected, and side effects must be safe.”
This one answer decides a lot. The system will promise that every due job is attempted at least once, and the job’s own code will be responsible for not causing double effects. You will not promise that each job runs exactly once, because no network call can honestly promise that.
You: “How long do jobs run? Seconds, or tens of minutes? That decides how long a machine may hold a job before others may take it over.”
Interviewer: “A mix. Most take seconds, and some run ten to thirty minutes.”
So there will be short jobs and long jobs, and they cannot be treated the same. A short job can be held for a short time. A long job needs a way to say “I am still alive” while it works.
You: “When a client submits a job, should the API wait until the job finishes, or answer as soon as the job is saved?”
Interviewer: “Answer once it is saved. Execution is asynchronous.”
The web request only has to make the promise durable. It does not hold a worker, and the client later asks for the status.
You: “Roughly how big is this? How many jobs a day, how many workers, and is there a peak?”
Interviewer: “Millions of jobs a day, about 10,000 workers, and a spike of around 50,000 jobs due at the top of the hour.”
Those numbers feed the capacity estimate in the next section. They also tell you early that the top-of-the-hour spike, not the daily total, is the hard part.
You: “I want to keep full workflow engines like Airflow, stream processing, and scheduling that runs inside the customer’s phone or browser out of scope so we can focus on the server-side scheduler. Does that match what you want?”
Interviewer: “Yes, the core scheduler.”
If the interviewer later asks about queue brands or sharding by tenant, you do not need to answer yet. Park those until the design decisions, where each one has a natural place.
Functional requirements
Functional requirements describe what the system does. From the answers above, a job scheduler must:
- Accept a job and make the promise durable. A client submits what to run, when to run it, and how important it is. The system saves it before answering, so a restart cannot lose it.
- Support one-off and repeating jobs. A job can run once at a given time, or follow a schedule such as every hour, and each repeat must fire once, not twice.
- Run due jobs on workers. When a job becomes due, some worker picks it up and executes it, and no two workers execute the same attempt at the same time.
- Respect priority. A payment check must be able to run ahead of a pile of marketing emails, without letting the emails wait forever.
- Retry failures and park hopeless jobs. A job that fails for a short reason is tried again after a delay. A job that keeps failing is set aside for a person.
- Cancel a job and report its status. A client can cancel a job that has not run yet and ask whether a job is waiting, running, done or failed, and what went wrong.
Non-functional requirements
Non-functional requirements describe how well the system must do its job. They are the numbers and promises that shape the design.
- Durability. Once the client is told “accepted”, the job must not be lost, even if a scheduler machine, a worker or the database primary fails right afterwards.
- Reliability of running. A due job runs at least once. If a worker dies halfway, the job is picked up again, so the job’s own code has to tolerate a second try.
- Availability. The scheduler stays up about 99.9% of the time. A short failover may delay jobs by seconds, but it must not lose them or fire them twice.
- Timeliness. A job should start within a stated number of seconds after it is due. “Exactly at the second” is not a realistic promise when thousands of jobs are due together, so say the number you can defend.
- Fairness. Each team gets a fair share of workers, so one team cannot fill all of them while others wait.
- Scale. Millions of jobs a day, about 10,000 workers, and a burst of about 50,000 due jobs at the top of the hour.
- Visibility. The team must be able to tell whether the scheduler is healthy by watching how late jobs are, not only how busy the machines are.
Out of scope (and why you park these)
Write a short out-of-scope list on the board so the interviewer sees you can bound the problem.
Full workflow orchestration (Airflow-class). Graphs of jobs that wait on each other, a backfill screen, and libraries of ready-made steps are a different product layer. Mention that a child job can be released when its parents finish, and design the simple start-and-run path first.
Stream processing (Flink, Kafka Streams). Those tools handle endless flows of events, which is a different problem from starting discrete jobs at known times.
Scheduling that lives only on the client. Phones and browsers sleep, lie about the time and disappear. The server must own the schedule, otherwise nothing is a promise.
Exactly-once side effects with no help from the job’s code. A scheduler cannot make someone else’s webhook run exactly once. You park the debate by committing to safe duplicates up front, and the decisions below show how.
That is the requirements stage. If you want to practice it before reading on, try the requirements stage on Practice System Design (about 5–10 minutes), then come back for the sizing and the decisions.
Minute pacing (about 45–50 minutes)
| Minutes | Focus |
|---|---|
| 0–5 | Clarify the problem; write functional and non-functional requirements; agree out of scope |
| 5–12 | Capacity, then the design decisions and the high-level boxes with one job’s story |
| 12–22 | Data model, the path of one job, and the choice between a database as the queue and a separate queue |
| 22–32 | The deep dive: worker crash mid-job, leases, safe duplicates |
| 32–40 | Repeating schedules, the crowd at :00, failure table, API, what you measure |
| 40–48 | One production story and the tradeoffs |
| 48–50 | Questions |
In the room (how you open): “I would start by agreeing what kinds of jobs we run: one-off or repeating, short or long, and what promise the product needs about running them. I would ask whether the caller waits for the result, how many jobs and workers there are, and where the peaks are. I will write the functional and non-functional requirements on the board and agree what is out of scope, then size the problem, and only then make the design decisions one at a time, so every box I draw has a reason.”
If you remember one thing: Ask first, write the requirements down, and only then design. Tell one job’s story before you recite queue names.
Capacity estimation
Once the requirements are clear, the next step is to find out how big the problem is, because the size decides how simple the first design can be. The daily totals turn out to be modest. The real pressure comes from the top of the hour, when many jobs are due in the same second.
Rough numbers to anchor the whiteboard (these are estimates; tune them in the room):
| Load | Order of magnitude | Design implication |
|---|---|---|
| Future scheduled jobs | 100M+ rows (estimate); at about 1 KB of metadata each, roughly 100 GB | Time-indexed queries; partition by tenant or time; never scan the whole table on each tick |
| Executions per day | About 10M attempts, which is roughly 115 per second on average | The average is easy; size for the peak, not the average |
| Workers | About 10,000 | Workers must claim jobs without a central bottleneck; pulling work scales better than pushing it |
| Top-of-hour burst | About 50,000 jobs due in one second, which is 50,000 per second if nothing spreads them out | Without spreading, this is a spike of hundreds of times the average; with a spread over 5 minutes it is roughly 170 per second |
| Draining the burst | 50,000 short jobs over 10,000 free workers is about 5 jobs per worker | Fine if workers are free, painful if they are busy with long jobs, which is why long jobs get their own pool |
| Execution history | About 10M rows a day at about 300 bytes is roughly 3 GB a day, or about 1 TB a year (estimate) | Partition by time, archive successes, keep failures longer |
| Heartbeats | 10,000 long jobs each reporting every 60 seconds is about 170 writes per second | Small at that rate; it grows if workers report every few seconds, so choose the interval on purpose |
What the numbers imply
- The schedule lookup must cost “how many are due”, not “how many exist”. With 100M+ future rows, a scan on every tick would never finish. An index on the next run time makes each tick read only the rows that are actually due.
- The burst is the real design input. An average of about 115 attempts a second is trivial. Fifty thousand due in a single second is not, so spreading starts and keeping urgent work apart from bulk work are core parts of the design, not extras.
- Time to start is the number users feel. Judge the system by how long the oldest due job has waited, not by the CPU graph of the workers, because CPU can look calm while a queue is already late.
- The execution table grows fastest. Keep it partitioned by time, and keep large payloads in object storage with only a pointer in the row.
- The scheduler has little to do per tick. A tick that reads a bounded batch of due rows is cheap, so the first version does not need heavy machinery. Heavy machinery becomes necessary only when the tick or the claims start to compete for the same database.
Checkpoint: Which number is the real problem, the daily total or the burst, and why?
If you remember one thing: Index for next due, plan history growth, and treat the top of the hour as a capacity event unless something spreads it.
Design decisions
We now know what the system must do, how reliable it must be, and roughly how big it is. Now we choose. Each decision below answers one question that the requirements raised, and each one rules out an easier idea that would not survive the requirements. Read them in order, because every decision builds on the one before it.
Decision 1: Where does the promise to run a job live?
The requirements said that once the client hears “accepted”, the job cannot be lost, even if machines restart. So the first question is where a job exists between the moment it is submitted and the moment it runs, which could be a second or a month.
The simplest idea is the one everyone knows from a single computer: a crontab, a list of times kept in a file on one machine, with a program that wakes up and runs things. A close cousin is a timer inside a server’s memory that fires when the time comes. Both are fast and need nothing else. Both fail the durability requirement. If that machine restarts, the timers in memory are gone, and a job promised for next Tuesday is silently forgotten. If the machine is replaced, the crontab goes with it. There is also no shared record, so nobody can answer “did this run?”
The choice is to store each job as a row in a durable store, a database that keeps its data on disk and copies it to other machines, with the time it should next run written on the row. The API saves the row, and only then answers “accepted” (HTTP status 202, which means “received and will be handled later”). It does not wait for a worker. This is the split that the rest of the page rests on: when a job should run is a durable fact in the database, and who runs it is decided later, by whichever worker is free.
A client can double-click or a phone can retry a submit, so the request also carries an idempotency key, a unique id the caller picks for this submission. If the same key arrives again, the API returns the same job id instead of creating a second job that would fire twice.
Decision 2: How does the system notice that a job is due?
Jobs are now stored with a next run time. Something has to notice when that time arrives, because a database row does not wake itself up. Remember the size: more than 100 million future jobs, and about 115 attempts a second on average.
The simplest idea is one timer per job. When a job is saved, start a timer that fires at its time. With millions of timers this costs a lot of memory, the timers die with the process, and rebuilding them after a restart is a slow scan of everything. The second simple idea is to look at every job every second and ask “is it due?” That is a full scan of 100 million rows every second, which would melt the database.
The choice is a tick loop: a small scheduler process wakes up regularly, every second or so, and asks the database for jobs where the next run time is now or earlier, using an index on that column so only due rows are read. It reads a bounded batch (for example a few thousand rows at a time), because one tick that tried to load millions of due rows would use all its memory and time. The cost of a tick then depends on how many jobs are due, not on how many exist. If one scheduler machine cannot read fast enough, the work is split between several by tenant or by hash, which the core design approaches section covers. Because the real time of a job is stored in the database, the tick compares against one clock instead of trusting the wall clock of every machine.
Decision 3: How do due jobs reach the workers?
When a tick finds due jobs, they must get to the right machines. With 10,000 workers, two questions follow: where do the ready jobs wait, and who starts the conversation, the scheduler or the worker?
The simplest answer is that the scheduler tells a worker directly, called push: it picks a worker and sends it the job. It is quick, but the scheduler now has to know which workers exist, which are free, and what to do when one does not answer, and a retry from the scheduler can send the same job to two workers. The other direction is pull: ready jobs wait in one place and each worker asks for the next one when it has free capacity. Pull scales by adding workers, and it slows down by itself when workers are full, because a full worker simply does not ask.
So the choice is pull. Where should the ready jobs wait? There are two reasonable places.
- The database itself, used as a queue. Workers ask the same database for a ready row, and a feature such as
SELECT … FOR UPDATE SKIP LOCKEDlets each worker take a different row without waiting for the others. It has one system to run and one source of truth. - A separate queue such as Kafka or SQS. It smooths bursts, has retry and dead-letter features built in, and lets the tick rate and the worker speed differ. The price is a second system, and the job store and the queue must now stay consistent, which needs a pattern called an outbox (one transaction writes the job and a “please enqueue me” note, and a small relay publishes the note afterwards).
At first, the database as a queue is simpler and is the first choice for moderate load. Move the ready work to a separate queue when the tick or the claims start fighting for the same database primary, and not on day one by default. The next decision is about the part both options share: taking ownership of one job.
Decision 4: How does a worker take a job, and keep it?
Ready jobs are waiting and workers are asking. Now we need the rule that makes sure one worker owns one attempt of a job, because the requirements said no two workers may run it at the same time, and also that a job must not stay stuck when its worker dies.
The simplest idea is to hand out the job and forget it: send it to a worker and consider it done once the call returns. This fails in the way that matters. If the worker crashes at minute four of an eight-minute job, nobody knows whether the job finished, never started or is half done. The scheduler either gives up and loses the job, or sends it again blindly while the first worker may still be running it.
The next idea is a plain lock: the worker marks the job “running”, and nobody else touches it. That fixes two workers at once, but it creates the stuck problem. A lock has no end, so a worker that dies leaves the job “running” forever.
The choice is a lease, a lock that expires. When a worker claims a job, it writes its own id and a deadline, locked_until, on the job’s row, for example five minutes from now, and it raises a counter called lease_version. Nobody else may take the job until the deadline passes. A worker with a long job sends a heartbeat, a small update every minute or so that pushes the deadline forward, saying “I am still alive and still working”. If the worker dies, the heartbeats stop, the deadline passes, and another worker may claim the job with a higher lease_version. A late message from the old worker, carrying the old version, can then be recognised and ignored.
A short job gets a short lease and a long job a longer one with heartbeats, so a ten-minute export does not lose its claim at thirty seconds while still running. The deep dive shows this under a real crash.
Decision 5: What happens when a job fails?
A job can fail for a short reason, such as a network blip at the customer’s server, or for a lasting one, such as a bad request that will never work. The requirements said a failed job is tried again a few times and then set aside for a person.
The simplest idea is to try again immediately and keep trying. If the customer’s server is down, thousands of jobs hammer it every few milliseconds, which makes its outage worse and burns our workers. The opposite idea, never retrying, loses jobs that would have worked a minute later.
The choice is a limited number of retries with growing gaps. Each failure increases an attempt counter and schedules the next try later, using exponential backoff (the wait doubles each time, with a cap, for example 10 seconds, then 20, then 40) plus a little random delay so retries do not all return together. After a maximum number of attempts, the job moves to a dead-letter queue, a holding area for jobs that keep failing, with the error attached and an alert to the person on call. A person then decides whether to fix the cause and replay the job. Replay is manual or limited on purpose, because replaying every parked job at once can flood the same struggling customer system again.
Decision 6: How do we make a duplicate safe?
Decision 4 narrows the chance of two workers running the same job, and Decision 5 deliberately runs a job again after a failure. Neither can make duplicates impossible, and the requirements already accepted that a due job runs at least once. So the question is what happens to the customer’s money or inbox when the same job really does run twice.
The simplest wish is “run each job exactly once”. It cannot be delivered on a network. Picture a worker that calls the customer’s server, the server charges the card and answers “done”, and then the worker crashes before it records that. From the outside, the work happened but nobody knows it, so the lease expires and another worker must run it. A system that avoids this by never retrying would lose jobs instead.
The choice is to be honest about the two layers: delivery is at-least-once, and the effects are made safe to repeat. The scheduler sends the job id, the attempt number and the lease version with every call. The job’s own code stores a unique record for each real effect, such as (job_id, “charge”), and if the same effect arrives a second time it does nothing and still answers success. This property, where doing the same thing twice has the same result as doing it once, is called being idempotent. The scheduler promises that duplicates are rare, and the handler promises that duplicates are harmless.
Decision 7: How do repeating schedules fire once, and not all at the same second?
A repeating job, such as “every hour on the hour”, creates a new occurrence over and over. Two problems come from this, and both come from the requirements: each occurrence must fire once even if the scheduler is replaced, and thousands of jobs sharing the same pattern must not all become due in the same second.
The first problem appears when the scheduler machine that turned the midnight occurrence into a ready job dies a moment later. A new scheduler takes over, sees that midnight has passed and the next run time has not moved yet, and creates the midnight job again. The simplest idea, trusting that only one scheduler is alive, fails exactly during a failover. The choice is to give each occurrence a dedupe key, the pair (cron_id, occurrence_time), with a uniqueness rule in the database, so a second attempt to create the same occurrence is refused. Creating the occurrence and moving the schedule’s next run time forward happen in the same transaction, so there is no half-finished state. As a second safety net, a scheduler that was replaced carries an old fencing token, a number that grows with each new scheduler, and writes carrying the old number are rejected.
The second problem is the top-of-the-hour crowd. If a million jobs say “0 * * * *”, they all become due together, the tick returns a huge batch, and the urgent payment check waits behind the emails. The simplest idea is to buy enough workers for the peak, which is expensive and still leaves the downstream systems hit all at once. The choice is jitter, a small random offset added to each job’s first run time, for example spread over five minutes, so 50,000 simultaneous jobs become roughly 170 a second. Where exact timing matters, the offset is small or zero, and the stated promise is “within N seconds of the time”.
Decision 8: Who goes first, and who gets a fair share?
The last decision is about order. The requirements said a payment check must be able to run ahead of marketing emails, that one team must not take every worker, and that a ten-minute job must not block thousands of one-second jobs.
The simplest idea is one first-come-first-served line. It fails the payment check immediately, because it waits behind all the emails ahead of it. The next idea, strict priority, always serving the most important job first, protects payments but can starve everything else for as long as important work keeps arriving.
The choice is a few separate lanes with rules between them. Urgent work, bulk work and long-running work wait in different lanes, each with its own workers, so a long export cannot occupy the workers that handle short webhooks. Within the system, low-priority jobs get aging, which means the longer a job waits, the more important it becomes, so it cannot wait forever. Each team also has a concurrency cap, a limit on how many of its jobs may run at once, so one team cannot fill all 10,000 workers. These rules are simple to state and cheap to check when a worker asks for work.
Putting the decisions together
Taken together, the eight decisions are the design. A job is saved in a durable store with its next run time, and the client is told “accepted”. A tick loop reads small batches of due jobs through an index. Ready jobs wait in lanes, and workers pull from them. A worker claims a job with an expiring lease and keeps it alive with heartbeats while it works. Failures are retried with growing gaps and end in a dead-letter queue. Every effect the job causes is safe to repeat. Repeating schedules create each occurrence once, with a spread-out start time.
In the room (a fuller opening you can actually say): “I would persist every job with its next run time in a durable store and return accepted right away, so the clock lives in the database and not in a machine’s memory. A scheduler tick reads a bounded batch of due rows through an index on the next run time and puts them into ready lanes, so urgent payments are not stuck behind bulk emails. Workers pull jobs and claim each with a lease, an expiring lock, and send heartbeats for long jobs, so a dead worker’s job becomes available again without two live workers owning it. Delivery is at-least-once, so the job’s own code is idempotent, and failed jobs are retried with backoff and parked in a dead-letter queue with an alert. For repeating jobs I would give each occurrence a unique key so a scheduler failover cannot fire midnight twice, and add jitter so the top of the hour is not a stampede. I would start with the database as the queue and move ready work to a separate queue when the tick or the claims make the primary hot.”
The next section draws these decisions as one picture and shows who owns what.
High-level architecture
The decisions above were made one at a time. This section puts them on one page as a picture: which boxes exist, who owns what, and how one job travels through them. The deeper mechanics come later, so keep this at the level of a map.
The API is the front door that creates and updates jobs. It writes them into a durable store — a database that keeps data on disk and copies it to other machines — and answers before any worker runs. One or more scheduler processes, often with a single elected leader, run a tick loop: every second or so they ask for jobs whose next run time is now or earlier (using an index on that time), and either put those jobs into a ready queue or, if the database itself is the waiting line, mark them claimable. Workers pull ready jobs and claim each with a lease — a timed lock that records locked_until and worker_id — then run the user’s work (an HTTP callback, a container, or a script), and acknowledge success or report failure so a retry can be scheduled. Every attempt appends a history record, and jobs that keep failing end up in the dead-letter queue (DLQ), a holding area for a person to inspect.
Who owns what:
- Scheduler leader — Advances repeating schedules and turns due jobs into ready work. It must not create the same occurrence twice, so occurrences have a unique key
(cron_id, occurrence_ts), and a fencing token protects against an old leader. - Ready queue — Holds runnable jobs, separates tick speed from worker speed, and shows pressure through its depth and the age of its oldest job.
- Workers — Hold no important state of their own, so you add more of them to scale. They respect the lease and extend it by heartbeat on long jobs.
- Execution store — Keeps the history of attempts, statuses and error details for support and audits. It may share the database or stream to analytics.
[ Clients / services ]
        |
        | POST /jobs (sync: persist only → 202)
        v
[ Job API ] ──write──► [ Job metadata DB ]
        |                    ^
        |                    | next_run_at index
[ Scheduler Leader ] --------┘
        |
        | tick: due rows → enqueue (async)
        v
[ Ready queue: Kafka / SQS / DB SKIP LOCKED ]
        |
        v
[ Worker pool ] ──lease + heartbeat──► [ User workload ]
        |                                    |
        | fail max retries                   v
        v                              [ DLQ + alert ]

  Cron: scheduler expands next occurrence → same pipeline (with dedupe + jitter)
In the room: Say the async boundary clearly: HTTP returns 202 after the job is saved, and execution happens later. Then describe lease, retry and DLQ before diving into repeating schedules.
If you remember one thing: The API saves, the scheduler turns due rows into ready work, and workers claim with a lease.
Core design approaches
The picture raises a few choices that deserve a closer look, because the interviewer may ask why you picked one side. Some were introduced in the decisions; here they are side by side so you can defend the pick without redesigning from scratch.
Database-as-queue vs external queue
Database polling with SELECT … FOR UPDATE SKIP LOCKED (Postgres) or something equivalent can work at moderate scale. Workers ask the same database for a ready row, lock a different row from everyone else, and run it. You run one system of record, which is simpler on day one. It becomes painful when the scheduler tick and the worker claims compete for the same primary database, because both paths are writing and locking hard.
An external queue such as Kafka or SQS adds a second system to operate, but it smooths the top-of-hour burst, brings a standard retry and dead-letter path, and lets the scheduler tick and the workers move at different speeds. The price is keeping the job store and the queue consistent, which is why an outbox (write the job and a “please enqueue me” note in one transaction) matters.
| Approach | When to pick | What breaks first |
|---|---|---|
| DB-as-queue | First version, moderate rate, strong consistency wanted | Primary gets hot from tick plus claim |
| External ready queue | Burst at :00, many workers, queue-native DLQ wanted | Operations load; dual-write without an outbox |
| Hybrid | Metadata in the DB, ready work in the queue | Needs an outbox or transactional enqueue discipline |
Say in the interview: Start with the database as the queue if scale is modest. Move ready work to Kafka or SQS when tick duration or claim contention hurts, not on day one by default.
Single leader vs sharded schedulers
A single leader that runs the tick is easy to reason about: one process creates each repeating occurrence, so dedupe is simpler to explain. That choice fails when one leader cannot read enough due rows per second to keep up with the burst. Then you split the schedules by hash(tenant_id) or by key range, so each shard owns a slice of the work, runs its own tick, and still dedupes inside its own slice with its own fencing token. Say out loud that sharding is a response to tick pressure, not a day-one decoration.
Push vs pull workers
Pull means ready jobs wait in one place and each worker asks for the next job when it has free capacity. That scales by adding workers, and it slows down by itself when workers are full, because a full worker simply does not ask. Push means the scheduler picks a worker and sends the job. That can look faster, but the scheduler must know which workers exist and which are free, and a retry from the scheduler can send the same job to two workers (double dispatch). Prefer pull for this interview unless the interviewer forces a push story, and if you push, name the double-dispatch guard.
Priority and fairness
A single first-come-first-served line fails the payment check behind a pile of emails. Strict priority — always serve the most important job first — protects payments but can leave bulk work waiting forever whenever important work keeps arriving. The durable answer is a few separate lanes (urgent, bulk, long-running), each with its own workers where needed, plus aging so a low-priority job becomes more important the longer it waits, and a concurrency cap per team so one tenant cannot fill all 10,000 workers. Weighted fair queueing is the same idea with a share of capacity per lane; name the mechanism you would actually build.
Dependency execution (brief)
Some products have jobs that wait on other jobs. The thin version for this interview is enough: store the parent links, mark a child ready only when every parent has finished successfully, and when a parent succeeds, unblock its children with an event instead of asking “are my parents done?” every second. Full workflow engines with backfill screens and operator libraries stay out of scope unless the interviewer opens them.
If you remember one thing: The database as the queue is simpler until the tick gets hot. A separate queue adds operations work but smooths the :00 burst and gives a dead-letter path.
Data model
The decisions mention a next run time, a lease, a dedupe key and a dead-letter area, so the next question is what exactly gets stored. “We use a queue” is not yet a design until the fields are named.
One job first: A client submits “send the monthly invoice, every month, high priority”. That becomes one row in jobs with a next_run_at. When it is due, one row appears in executions for attempt 1, and the job row carries the lease while a worker holds it. The tables below are those pieces in full.
jobs (schedule + payload metadata)
| Column | Role |
|---|---|
job_id | Primary key; correlation id for callbacks |
tenant_id | Fairness, sharding, quotas |
status | PENDING, RUNNING, COMPLETE, FAILED, CANCELLED |
schedule_type | once, cron, interval |
cron_expr / interval_sec | Recurrence definition |
next_run_at | Indexed; the scheduler tick queries due rows |
priority | Queue lane or ordering hint |
payload_ref | Pointer to a blob in object storage, not megabytes inline |
max_attempts | Cap before the DLQ |
idempotency_key | Client-supplied dedupe on create |
created_at, updated_at | Audit |
Repeating-schedule dedupe: When creating an occurrence, insert or enqueue with a unique (cron_id, occurrence_ts) so a leader failover cannot create two runnable rows for the same minute.
executions (attempt history)
| Column | Role |
|---|---|
execution_id | Per attempt |
job_id | Link to the job |
attempt | Rising retry count |
worker_id | Who claimed it |
lease_version / fencing_token | Stale worker detection |
started_at, finished_at | Latency, SLO |
status | RUNNING, SUCCESS, FAILED, LEASE_EXPIRED |
error_code, error_blob | DLQ forensics |
Partition by time; this table grows fastest.
Lease fields (on the job row or a claim table)
| Field | Role |
|---|---|
locked_until | Time after which the claim expires (use the database’s own clock) |
worker_id | Current owner |
lease_version | Rises on each claim; a callback with an old version is rejected |
Heartbeat: UPDATE … SET locked_until = now() + interval WHERE job_id = ? AND worker_id = ? AND lease_version = ?. If it updates zero rows, the worker lost the lease and must stop.
cron_next_run (optional normalization)
Some teams keep last_occurrence_at and a computed next_run_at on the schedule row, and the tick advances next_run_at after creating the occurrence successfully. For jitter, store jitter_sec and set the first fire to base_time + random(0, jitter_sec).
DLQ
| Field | Role |
|---|---|
dlq_id | Entry id |
job_id, final_attempt | Link back |
reason | Poison, max attempts, manual kill |
payload_snapshot | For replay forensics |
replayed_at | Guard against accidental DLQ loops |
If you remember one thing: The next_run_at index, lease columns, the occurrence dedupe key and the DLQ are first-class tables, not details hidden inside the queue product.
Detailed design
We now know what is stored and where the rules live, so we can put the pieces in motion. This section follows one job from “a customer scheduled it” to “a worker finished it or gave up”, so you can hear how the pieces talk to each other and not only which tables they touch. After the story it shows the same system from the client’s side, as the API.
The path of one job, step by step
Scheduling the job. A client submits what to run (a payload or a webhook address), when (right away, delayed, or on a repeating schedule), how important it is, and an idempotency key. That key is how the system survives a phone retry or a double-click: if the same key arrives twice, the API returns the same job id and does not create a second row that would fire twice. When the request is new, the API writes the job in a waiting state (PENDING), works out the first next_run_at, and answers quickly with 202 Accepted, so the client does not wait for a worker. A repeating job gets its next fire time from the schedule pattern, with a little jitter so thousands of “every hour on the hour” jobs do not wake in the same second. If the product has jobs that wait for parent jobs, store the links and mark a child ready only after all parents succeed, and keep that story brief unless the interviewer expands scope.
When the job store and the ready queue are separate systems, use an outbox: in one database transaction write both the job row and a note saying “please enqueue me”, and let a small relay publish to the queue afterwards. This exists because “saved in the database but never handed to workers” is a classic crash bug when the job is published before the commit finishes, or when the client is answered before both writes land.
Noticing the job is due. Something has to wake work when next_run_at arrives. That can be a leader process, a sharded set of tickers, or a delay queue; name your choice. On each tick, load a bounded batch of due rows (next_run_at <= now(), with a page limit) so a tick cannot enqueue millions of messages and melt itself. For each due job, create a ready message or an execution record. For repeating schedules, use the dedupe key (cron_id, occurrence_timestamp) with a uniqueness rule, so a leader failover cannot create “midnight billing” twice, and move the schedule’s next run time forward in the same transaction. If you use a single leader, protect ticks with a fencing token so an old leader that lost the election cannot keep writing.
Taking ownership. Workers either pull from the queue or poll the database. Either way, claiming must be exclusive. A common database pattern is to find one ready row whose lease has expired or is unowned, lock it (FOR UPDATE SKIP LOCKED), and mark it RUNNING with locked_until = now + lease_ttl, a worker_id and a rising lease_version. The worker then does the real work, often an HTTP call to the customer’s system, passing the job id, the attempt number and the lease version so the receiver can ignore delayed duplicates. If the call succeeds, the worker marks the job COMPLETE, records a successful execution and acknowledges the queue message so it will not come back.
When it fails. If the call fails in a way that might be temporary, such as a timeout or a 5xx error, the worker raises the attempt count, sets next_run_at with exponential backoff, and returns the job to waiting, or lets the queue’s retry policy do that. After too many attempts the job moves to the dead-letter queue (DLQ) with an alert. Humans decide whether to fix and replay it, because silent retries forever are how you burn a vendor’s API overnight.
Long jobs. Some work lasts minutes or hours. Give those a longer lease and require the worker to send heartbeats that push locked_until forward. If the heartbeats stop, the lease expires and another worker may claim the job, so the job’s code still needs an idempotency story (or checkpoints) so a second claim does not double-charge or double-email. Keep long jobs on a separate pool if they would starve short ones.
- Save the job with
next_run_at, answer 202. - Each tick reads a bounded batch of due rows and creates ready work, with dedupe for repeating schedules.
- A worker claims one with a lease.
- It sends heartbeats while it runs.
- It calls the customer with the job id, attempt and lease version.
- It acknowledges and marks COMPLETE, or schedules a retry with backoff, or sends the job to the DLQ.
Client POST /jobs → persist PENDING → 202 + job_id
        ↓
Scheduler tick → ready queue (deduped for cron)
        ↓
Worker claims with lease → optional heartbeats
        ↓
Customer callback → success: COMPLETE / failure: backoff → or DLQ
API design: what clients send, what the scheduler sends, what operators do
A job scheduler is itself an API that other teams call, so the API design covers three things: the calls clients make, the call the scheduler makes to the customer’s system when a job runs, and the controls operators use.
What clients call.
| Endpoint | Role |
|---|---|
POST /v1/jobs | Create; body: schedule, payload, priority, retry_policy; header Idempotency-Key |
GET /v1/jobs/{id} | Status, next_run_at, attempts, last error |
DELETE /v1/jobs/{id} | Cancel future runs; optionally signal a running worker (SIGTERM or lease revoke) |
GET /v1/jobs/{id}/executions | Attempt history for support |
What the scheduler sends when a job runs (worker to customer system). The worker calls the customer’s webhook with headers that let the receiver spot duplicates and verify the sender.
| Header / field | Role |
|---|---|
X-Job-Id | Correlation, and the key for the receiver’s dedupe |
X-Attempt | Retry count |
X-Lease-Version | Stale worker detection |
X-Scheduler-Signature | HMAC signature so the customer can verify the payload came from the scheduler |
Status codes and errors. A 202 on create means “accepted, not executed”, which is the honest answer because the job runs later. A 409 means the same idempotency key arrived with a different body. A 404 means an unknown job, and a 429 means the tenant exceeded its quota of creates or concurrent jobs. On the callback side, any 2xx means success, a 4xx that is not a throttle usually means the job is wrong and should go to the DLQ without endless retries, and a 5xx or a timeout means try again with backoff.
What operators change. A small admin API lets the team run a job by hand and manage parked work without touching the database.
POST   /v1/jobs/{id}/trigger        # manual run (admin)
GET    /v1/admin/dlq                # list parked jobs with sample errors
POST   /v1/admin/dlq/replay         # replay N at a time, gated and audited
POST /v1/jobs ──► 202 Accepted + job_id
                      │
Scheduler tick ──► ready queue ──► Worker ──► POST https://customer/callback
                                                  │
                                            200 ─► ack
                                            5xx ─► retry w/ backoff ─► DLQ
In the room: “A client creates a job with an idempotency key and gets a 202 and a job id, and the job runs later. The scheduler’s tick turns due rows into ready work, a worker claims it with a lease, and calls the customer’s webhook with the job id, attempt and lease version, signed so the customer can trust it. Success is acknowledged, a temporary failure is retried with backoff, and a job that keeps failing lands in the dead-letter queue, where an operator replays a few at a time.”
Deep dive: the questions an interviewer asks next
You have drawn the design and walked one job through it. This is the point where a good interviewer starts digging, and the questions usually come in a fairly predictable order, because each answer raises the next one. Read this section as that conversation. Each question is followed by an answer you can give in the room, plus a short hint of where the interviewer is likely to go next, so you can lead instead of waiting to be asked.
“What happens if a worker dies halfway through a job?”
Start with the version where nothing is done about it, because that is the red flag. Suppose the scheduler pushes a job to a worker over HTTP, with no lease and no saved “running” state, and treats the job as finished when the call returns.
t0  Worker W1 receives job J, starts an 8-minute export
t1  W1 crashes at minute 4 — no heartbeat, no locked_until
t2  Scheduler thinks J is lost OR re-dispatches blindly
t3  Worker W2 starts J again — customer webhook runs twice
t4  Duplicate charges, duplicate emails
The trouble is that nothing owns the job. There is no authoritative claim, so the system cannot tell “still running” from “never started”. Whatever it does next is a guess: either the job is lost, or it is run again while the first worker might still be alive, and because the handler was not built for repeats, the customer sees duplicate side effects.
Interview land: “Fire-and-forget cannot survive at-least-once delivery. You need a lease, an acknowledgement and safe repeats.”
Where it goes next: the interviewer will ask what you do instead, and how the lease really works.
“So how does the lease actually work?”
The worker that claims a job writes a deadline on the job’s row, and everyone else respects it. In numbers: the claim sets RUNNING, locked_until = now + 5 minutes and lease_version = 3. The worker then sends a heartbeat every 60 seconds that extends locked_until, but only if its worker_id and lease_version still match. The callback carries X-Job-Id, X-Attempt and X-Lease-Version. The worker acknowledges only after the COMPLETE status is written durably, and then the message is removed from the queue.
Now take the hardest moment, a crash after the customer already said yes but before the worker acknowledged.
t0  W1 claims J, lease_version=3
t1  W1 POST callback → customer returns 200, commits idempotent row
t2  W1 crashes before ack
t3  lease expires; W2 claims J, lease_version=4
t4  W2 POST callback → customer dedupe hit → 200 no-op
t5  W2 acks → COMPLETE once from business view
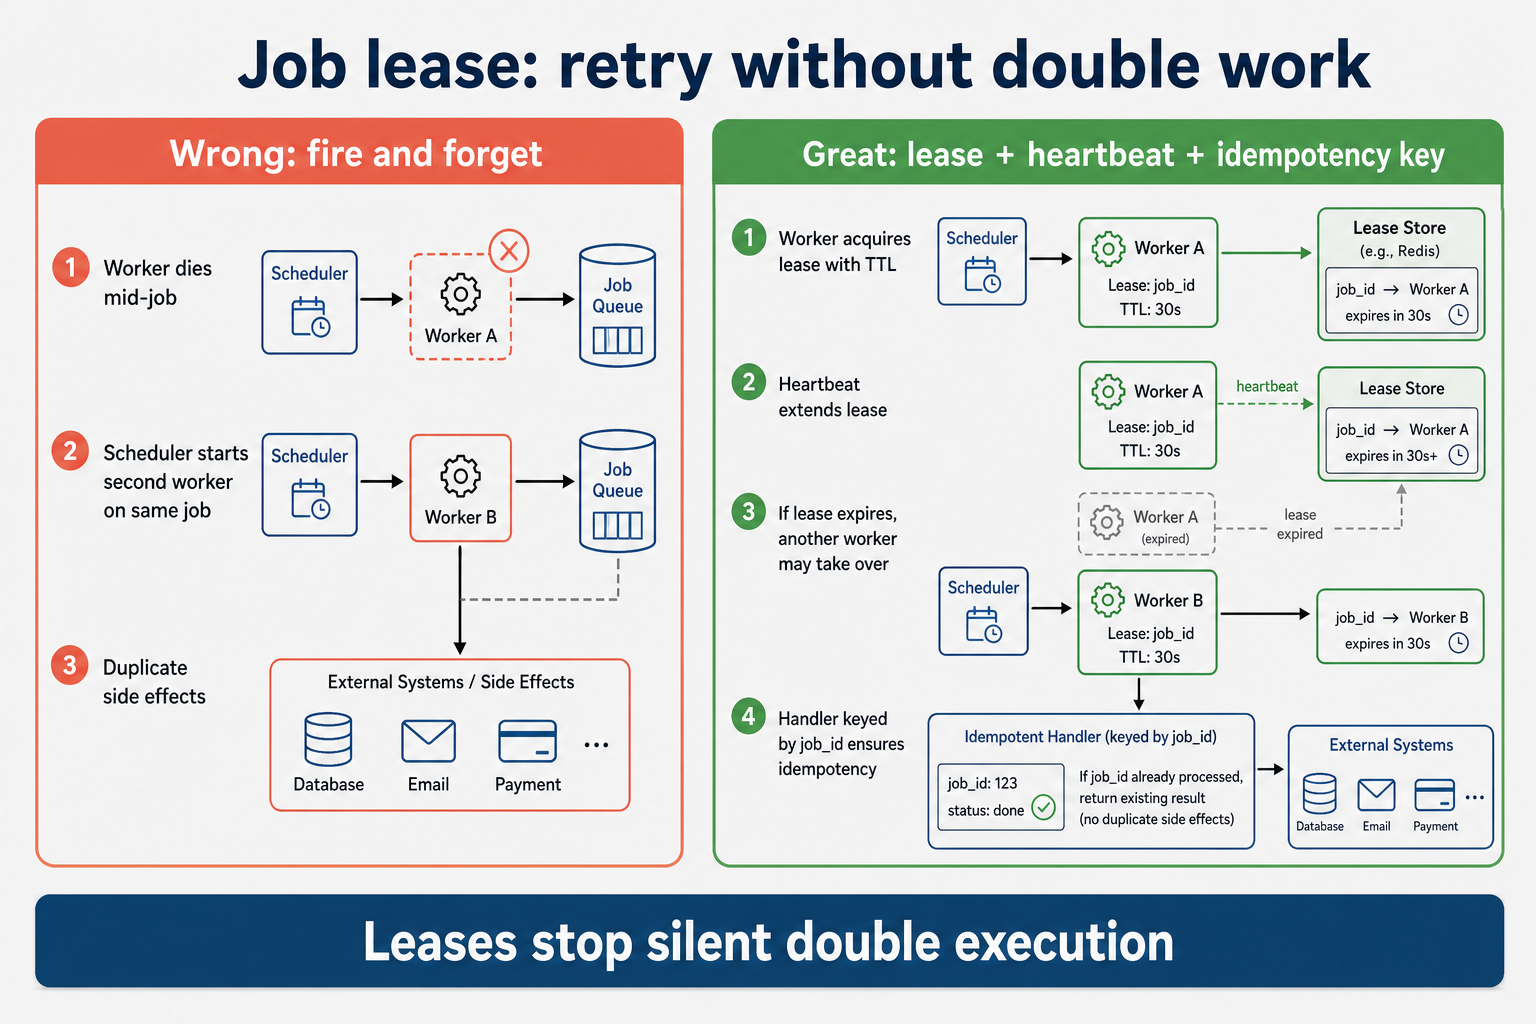
Figure: The lease limits how long a job can be stuck, and idempotency limits the harm when it runs twice.
The job ran twice from the system’s point of view, and once from the customer’s. Nobody saw half-finished state, because the customer’s own record of the effect turned the second call into a harmless “already done”. The lease did its part as well: it ensured that the job became claimable again only after the first worker had stopped sending heartbeats.
Where it goes next: “Can’t you just make it exactly once?”
“Can’t you guarantee exactly-once execution?”
Not on the wire. A queue or an HTTP callback cannot know whether a request that timed out was processed or lost, so a system that never retries loses work and a system that retries sometimes repeats it. Most managed queues are at-least-once for this reason. A queue message with a visibility timeout and no heartbeat has the same duplicate window: if the job runs for ten minutes and the message becomes visible again after thirty seconds, a second worker will pick it up while the first is still working.
What you can promise is effectively once, which means duplicate attempts but a single effect. Each real effect is stored under a unique key, such as (job_id, “charge”), in the customer’s database in the same transaction as the effect itself. A second attempt finds the key and returns success without doing the work again. If the customer’s system cannot be changed, an outbox on their side or a dedupe table in front of their webhook gives the same result. Say this sentence in the room before the interviewer pushes on crashes, because it shows you understand which layer owns which guarantee.
Where it goes next: “What breaks first with thousands of long jobs?”
“What breaks first with thousands of long jobs, and what about a worker that comes back late?”
The first problem is the volume of heartbeats. With 10,000 long jobs reporting every 60 seconds that is about 170 writes a second, which is easy. If the interval is dropped to 5 seconds to detect deaths faster, it becomes about 2,000 writes a second to the same table the tick and claims use, and that table gets hot. The answers are to batch several extensions into one statement, to choose a longer lease with fewer heartbeats, or to keep heartbeats in a fast store while keeping the job row as the source of truth. Pick the interval from how quickly a dead worker must be noticed.
The second problem is a stale worker, one that was thought dead but was only paused, for example by a long garbage-collection stop or a network partition, and wakes up after its job was given to someone else. It still believes it owns the job. This is why lease_version exists. When the old worker tries to write its result or heartbeat, the update names the old version, matches zero rows, and the worker learns it lost the lease and must stop. The same version in the callback lets the customer ignore the late call.
Where it goes next: “What about the scheduler itself failing over?”
“How do you stop two schedulers from firing midnight billing twice?”
The scenario is a leader that dies at 00:00:02, just after it created the midnight occurrence and before its bookkeeping finished, and a new leader that starts and sees the midnight occurrence is still due. Without protection both occurrences become runnable and billing runs twice.
There are two layers of defense. The first is a uniqueness rule on the occurrence, (cron_id, occurrence_ts), so the second insert is refused by the database, and the code treats “already exists” as success. A deterministic job id for each occurrence gives the same safety. The second is a fencing token, a number that grows each time a new leader is elected and travels with every write. The database rejects writes carrying an older number, so an old leader that is slow to notice it was replaced cannot do any harm.
INSERT INTO occurrences (cron_id, occurrence_ts, job_id)
VALUES (:cron, :ts, :deterministic_id)
ON CONFLICT (cron_id, occurrence_ts) DO NOTHING;   -- same transaction as moving next_run_at
Test this on purpose: drills that kill the leader at a schedule boundary are how teams discover that their bookkeeping is not atomic.
Where it goes next: “And the crowd at the top of the hour?”
“How do you avoid the crowd at :00?”
Take the numbers. If 50,000 jobs share the same pattern and become due in the same second, the tick returns a huge batch, the queue jumps from nothing to 50,000 messages, and the payment check is at the back of the line. Autoscaling reacts in minutes, long after the jobs have waited. Spreading the first run time of each occurrence with a random offset over a window of, for example, five minutes turns the spike into roughly 170 starts a second, which the existing workers absorb. Where a team really needs a precise time, keep their offset small or zero and put them in a separate urgent lane, so a spike in bulk work cannot push them back.
Jitter also helps outside our system. Every job that calls a customer’s server, a database or a payment provider would otherwise hit it at the same moment, so spreading the starts protects them too.
Where it goes next: “Can you tell me the whole thing in one breath?”
“Can you say the whole path in one breath?”
Yes, and it is worth rehearsing: “I save the job with its next run time and answer 202. A tick reads a bounded batch of due rows and creates ready work, once per occurrence. A worker claims a job with a lease and sends heartbeats while it runs. It calls the customer with the job id, attempt and lease version, and the customer deduplicates on the job id. Then the worker acknowledges and marks the job complete, or schedules a retry with backoff, or parks the job in the dead-letter queue after the maximum number of attempts.”
Say it in the interview: “Delivery is at-least-once. The lease narrows the window in which two workers can hold a job, and idempotent handlers make the remaining duplicates harmless. Repeating schedules are deduplicated by occurrence, so a failover cannot fire midnight twice.”
If you remember one thing: The deep dive is a conversation. Fire-and-forget is the red flag, a lease plus idempotent handlers is the fix, and each answer is something you could have said before they asked.
Key challenges
The deep dive showed that each core step is simple once it is protected. What makes the real system hard is everything around those steps, and a handful of hard parts show up again and again. Name them early in the interview, because each one is a place the interviewer is likely to push, and each one needs a mechanism you can draw — not only a product name.
- Double dispatch. Two scheduler leaders each think they own midnight, so both create the same occurrence and billing runs twice. Stop that with a uniqueness rule on
(cron_id, occurrence_ts), a fencing token so an old leader’s writes are rejected, and a deterministic job id for each scheduled minute as a second safety net. - Lost work. The API already answered “accepted,” then the process crashed before the job reached the ready queue, so a promise disappears while the client believes it is safe. Write the job and a “please enqueue me” note in one database transaction (the outbox pattern), and let a small relay publish afterwards so the store and the queue cannot disagree.
- Stuck RUNNING. A worker dies and the row still says “running,” so nothing else ever picks the job up. Give every claim a deadline that expires, extend it with heartbeats while the worker is alive, and make the job’s own code safe to run again when another worker claims it after the lease ends.
- The herd at :00. Millions of schedules share the same “on the hour” pattern, so the ready queue jumps from empty to huge while worker CPU still looks calm. Spread first run times with jitter inside a window, keep urgent work in its own lane, and add workers before known peaks instead of waiting for CPU to turn red.
- Priority inversion. A single line buries the payment check behind emails; strict priority can leave bulk work waiting forever whenever important work keeps arriving. Use separate lanes with aging or a fair share of capacity so urgent work moves first without starving everyone else.
- Long versus short jobs. One ten-minute export sitting in the same pool as one-second webhooks can block thousands of short jobs. Put long work on its own queue and worker pool so short callbacks keep moving.
- Noisy neighbors. One team submits enough jobs to fill every worker, and every other team’s payments wait. Cap how many jobs each tenant may run at once and dispatch fairly across tenants so one backlog cannot own the fleet.
If you remember one thing: Name double dispatch, lost enqueue, stuck RUNNING and the :00 herd, each with a mechanism, not a product name.
Scaling the system
Those hard parts get worse as the number of jobs and teams grows, so the next question is what happens when the load multiplies. You do not have to wait for the interviewer to ask. Right after you finish the design, say the scaling story yourself, then be ready for the follow-ups.
What you can say upfront: “Workers scale by adding more of them, and I would scale them on the age of the oldest waiting job, not only on CPU, because age is what users feel. The scheduler scales by splitting the tick by tenant or hash range and capping the batch size per tick, so no single leader melts the database. The job table is partitioned by tenant or time, and heavy tenants get their own shard or queue. Repeating schedules are spread with jitter so downstream systems see a smooth load. For several regions, I would keep each schedule owned by one region and say which region that is, instead of pretending to have one global clock.”
That one paragraph answers most of what follows. Here are the follow-ups, in the order they usually come.
Interviewer: “Traffic doubles next quarter. What do you change?”
You: “Workers first, because they are the easy half. They hold no important state, since the truth lives in the database and the queue, so I add more of them and nothing else changes. Then I check the scheduler and the database: tick duration, claim contention and storage growth. If the tick is still fast and the primary has headroom, nothing else changes either.”
Interviewer: “How do you decide when to add workers?”
You: “From the oldest runnable job’s age, because that is the delay a user actually feels. CPU can sit at thirty percent while a queue is already an hour behind, for example when workers are waiting on a slow customer. I scale when the age approaches the agreed number of seconds, and I scale before known peaks such as the top of the hour.”
Interviewer: “One scheduler is not keeping up with the due rows. What now?”
You: “I split the work, for example by
hash(tenant_id), so each scheduler owns a share of the schedules and ticks only over its share. Each shard still dedupes its own occurrences, and each has its own leader and fencing token. I also cap the batch size per tick so one slow tick cannot hold up the rest.”
Interviewer: “The database is getting hot from ticks and claims. What do you do?”
You: “That is the signal to move the ready work off the primary. I put runnable jobs into a separate queue, keep the job metadata in the database, and use an outbox so the two cannot drift apart. I would not read claims from a replica without very careful locking, because a replica can lag and let two workers take the same job.”
Interviewer: “One customer submits ten million jobs. What happens?”
You: “Per-tenant limits on creating jobs and on running jobs at once keep one customer from using every worker or filling the queue, and a 429 tells them they went over. A very heavy customer gets their own queue or shard, so their backlog does not delay other teams’ payments. The cost is a little more configuration and some idle capacity in their lane.”
Interviewer: “What about more than one region?”
You: “I would say which region owns each schedule’s next run time, because running the same clock in two regions causes double starts. Data-residency rules often decide that anyway. Cross-region failover of a schedule is possible, but it needs the same dedupe key and fencing, and I would state how many seconds a failover may delay jobs.”
If you remember one thing: Scale workers on queue age, and split the scheduler tick before one leader melts the primary.
Failure handling
Scaling answers “what if there is more load”. This section answers “what if something breaks”. Again, say it first. Failures here come from workers, from the customer’s system, from the scheduler and from the database, and what impresses an interviewer is that the answer was decided before the failure happened.
What you can say upfront: “Every failure has a decision made in advance. If a worker dies, its lease expires and another worker picks the job up, and because handlers are idempotent, the repeat is harmless. If the customer’s system fails, the job retries with exponential backoff and a maximum number of attempts, and then goes to a dead-letter queue with an alert, and replay is gated. If the scheduler leader dies, a new leader takes over, and the occurrence key and fencing token prevent a double start. If the queue backs up, we scale workers, drop the least important work first and delay materializing new schedules. If the database is slow, ticks and claims lag, and we tune indexes, shard, or move ready work off the primary. Late jobs are acceptable with an honest target. Lost jobs and endless retries are not.”
The follow-ups are about the details of those decisions.
Interviewer: “A worker crashes in the middle of a job. What happens?”
You: “Its heartbeats stop, so the lease deadline passes, and a reaper or the next claim sees that
locked_untilis in the past. Another worker claims the job with a higher lease version. From the customer’s side this can be a second call for the same job, so the handler dedupes on the job id and answers success. A late message from the first worker carries the old lease version and is ignored. The job is delayed by about one lease length, and nothing is lost.”
Interviewer: “The customer’s server returns errors for twenty minutes. What now?”
You: “Each job retries with growing gaps and a little random delay, so the customer’s server is not hit by every job at the same instant. After the maximum number of attempts the job lands in the dead-letter queue with its error and an alert. I would pause or slow retries for that destination if many jobs fail at once, similar to a circuit breaker, and fix or wait out the cause before any bulk replay.”
Interviewer: “The scheduler leader dies at midnight. Does billing run twice?”
You: “No. The new leader may try to create the same occurrence, but the unique occurrence key refuses the second one, and the fencing token rejects any late write from the old leader. The tick pauses for a few seconds during the failover, which is a delay and not a loss, and I would limit how fast the new leader catches up so it does not release a backlog all at once.”
Interviewer: “The queue has a huge backlog. What do you do?”
You: “First scale workers, since age is the real symptom. If that is not enough, protect the important work: keep the urgent lane moving, slow or pause the lowest-priority lane, and delay creating new occurrences of non-critical schedules until the backlog drains. I would say honestly that jobs are late, with a number, instead of silently dropping them.”
Interviewer: “The database primary is slow. What happens to the jobs?”
You: “Ticks and claims slow down, so jobs start later, but the jobs already saved are safe. I tune the index on the next run time, shard if needed, and move ready work to a queue so claims stop competing with the tick. Clients creating jobs see slower or failed submits, and a retry with the same idempotency key is safe.”
Interviewer: “An engineer clicks ‘replay all’ on the dead-letter queue. What goes wrong?”
You: “If the downstream was the cause and was only just fixed, replaying everything at once can knock it over again and refill the queue. Replay is gated: a small number at a time, with a circuit breaker, after the cause is fixed, and with different reason codes for bad payloads, which will never work, and temporary failures, which usually will.”
| Failure | Effect | Mitigation |
|---|---|---|
| Worker crash mid-job | Duplicate run after lease expiry | Idempotent handler; dedupe table; lease_version on callback |
| Queue backlog | Growing lag, late scheduled jobs | Scale workers; shed low-priority; delay schedule materialization when backlogged |
| Scheduler leader dies | Tick pauses for seconds | Failover; dedupe prevents double fire; rate-limit the catch-up |
| Customer callback returns 500 | Retry storm | Exponential backoff, max attempts, DLQ |
| Poison message | Endless retry loop | DLQ after max attempts; alert; gated manual replay |
| DB primary slow | Tick and claim lag | Index tuning; shard; move ready work off the primary |
Degraded experience: Jobs that start late during a backlog are acceptable if the target is honest. Lost jobs and unbounded retries are unacceptable, so durability and dead-letter discipline are the product.
fail attempt → backoff → retry (attempt++)
                │
                └── attempt >= max → DLQ + page on-call
If you remember one thing: A worker dying leads to lease expiry and a retry, which is normal. Poison jobs go to the DLQ, not to endless loops.
Observability (what you measure)
Failure handling said what to do when something breaks. Observability is how you notice the break before customers do, and that takes more than one number. Do not watch only worker CPU, because a green CPU graph can hide hours of waiting jobs while machines sit idle on slow customer callbacks.
| Signal | Why it matters |
|---|---|
| Queue depth + oldest runnable job age | Depth says how much work is waiting; age says how late the worst job already is — that is the delay people feel, and it beats CPU for the schedule target |
| Scheduler tick duration | If each tick takes longer and longer, the primary is melting or the due batch is too large before anyone sees queue age climb |
| Lease expiry rate without success | Leases ending without a successful finish usually mean workers are crashing or hanging, which is the stuck-RUNNING story starting |
| Retry rate + DLQ ingress | A rising retry rate with growing dead-letter traffic points at a poison payload or a customer system that is down |
| Schedule materialization lag | How far now is past next_run_at for due rows that are still not ready — the clock kept its promise, the scheduler did not |
| Attempts by tenant | Shows which team is flooding retries or filling the fleet, so fairness caps have something concrete to act on |
| Tick batch size vs enqueue rate | Tells you whether the top-of-hour herd is being absorbed or whether each tick is still dumping more than workers can drain |
Alert ideas: Oldest job age above the agreed target; a spike in dead-letter arrivals; tick duration p99 high (the slowest 1 in 100 ticks); a duplicate-execution report that lines up with lease expiries. In the room, say you would page on age and DLQ, not on CPU alone.
Security and abuse
Cost and scale assume the system is used as intended. A scheduler is also a way to make a company’s servers do work on demand, so this section covers how to keep it from being abused. Authenticate every job submit call, because anonymous creating of jobs is a cheap way to flood workers and fill the queue. Put per-tenant quotas on how fast jobs are created and how many may run at once, and return a clear “too many” response when a team goes over. Validate payload size at the door, and store large blobs in object storage with only a pointer in the job row, so one huge body cannot blow up the database. Sign callbacks to the customer’s system (for example with HMAC) so they can trust that a call really came from the scheduler and not from an attacker who guessed a URL. Do not log full payloads if they may contain personal data; log ids and error codes instead. Manual trigger and dead-letter replay need elevated roles and an audit trail, and replay rates should be limited, because replay storms have taken down real downstream systems.
Cost awareness
Security keeps the system from being abused; cost awareness keeps the design from wasting money while it works. Interviewers like to hear that you noticed the bill, not only the boxes. Every duplicate webhook can waste downstream money (text messages, payment fees, support time). Every stuck retry loop burns worker CPU and customer goodwill. Execution history at about a terabyte a year (estimate) is real storage cost, so archive successes to cheaper storage and keep failures longer. Per-message fees on an external queue add up at millions of jobs a day, and using the database as the queue saves money until tick contention forces the move. Jitter is cheap engineering that avoids buying a huge worker fleet just for the top-of-hour spike. Replaying the dead-letter holding area without a gate is an expensive way to cause a second incident.
Green Dashboard. Angry Users. The Production Mindset System Design Interviews Expect.
Everything so far describes how the scheduler should work on a good day. This section is about what happens on a bad day, told as short stories from the people who carry the pager (the on-call engineers). Textbooks teach boxes and arrows. On-call teaches this: the graph can look fine while jobs are late or duplicated.
A normal CPU graph can mean “everything is fine” or “the queue is an hour behind”. A calm queue can mean “nothing is due” or “the scheduler stopped creating jobs”. Interviewers like this gap because it separates a diagram from someone who has run the thing.
Four nightmares that look fine on a dashboard:
| What the dashboard shows | What is actually happening |
|---|---|
| Worker CPU is a neat comb and nothing is red | The oldest job in the queue has waited past its target every hour |
| Thousands of jobs say RUNNING and no errors | The workers that owned them died, and nothing returns the jobs |
| Billing succeeded at midnight | It succeeded twice, because two schedulers each created the occurrence |
| The DLQ was emptied successfully | A replay storm is now breaking the customer’s service again |
Scene 1: The :00 comb, where queue age goes red before CPU does
The moment: A company runs a platform where customers schedule jobs for the top of every hour. Every hour, work that was supposed to start right away waits longer and longer before a machine picks it up. Worker CPU graphs still show a neat comb and nothing is red. One morning, a payment reconciliation job sits behind a marketing email batch that turned 50,000 jobs into ready work in ten seconds, and billing is late while the machines look calm.
The trap: Millions of schedules share the pattern “minute 0 of every hour” and have no spread, so the tick returns a huge batch at once. Autoscaling reacts in minutes, long after the spike. The team’s alert is on CPU, which catches up eventually, while the age of the oldest waiting job already passed its target long before.
What to build: Add jitter within a window (for example five minutes either side), separate lanes by importance, scale workers before known peaks, and alert on the oldest runnable job’s age before CPU.
Scene 2: Stuck RUNNING, where the worker died but the row still says busy
The moment: A support team that depends on nightly exports reports that jobs have been “stuck for hours” and the reports never arrived. The dashboard shows thousands of rows marked RUNNING, and no living worker has logs for those job ids — the machines that owned them are gone, but the rows still look busy.
The trap: The system had no timed claim, or a lease longer than the job’s runtime with no heartbeat. The workers died, and the rows never returned to a claimable state. In a second variation, a heartbeat bug stopped extending leases while the process hung, so the claim looked alive on paper while the work had already stopped.
What to build: A mandatory locked_until with heartbeat extension, a reaper that marks LEASE_EXPIRED and requeues when locked_until < now(), a metric on RUNNING rows past their lease, and idempotent handlers so the retry the reaper causes is safe.
Scene 3: Double dispatch on leader failover, where midnight billing ran twice
The moment: A company runs its monthly billing at the start of the day. The scheduler leader died at 00:00:02, just after midnight. A new leader started, saw that midnight still looked due, and created the billing run again. Customers saw duplicate charges on their statements before anyone noticed the failover.
The trap: Both leaders created the same occurrence, because there was no unique (cron_id, occurrence_ts) on creation, or because a stale leader without fencing wrote after the new leader took over.
What to build: A dedupe constraint on creating occurrences, a fencing token on the leader’s term, a deterministic job_id per occurrence as extra safety, and failover drills at schedule boundaries.
Scene 4: The DLQ flood, where replay had no gate
The moment: A customer’s API returned 503 for twenty minutes. Every job that called it retried, reached its maximum attempts, and landed in the dead-letter holding area. An engineer saw the pile and clicked “replay all” to clear it. The customer’s API went down again under the flood, and the holding area refilled within minutes.
The trap: The dead-letter queue was treated as a free retry button, with no rate limit, no small canary replay, and no fix of the root cause first.
What to build: A dead-letter alert with sample errors, replay N at a time with a circuit breaker, a fix of the downstream cause before any bulk replay, and separate reason codes for poison jobs (a bad payload that will never work) and temporary failures (a 503 that usually will).
[ Enqueue rate >> process rate ]
        → ready queue depth ↑
        → age SLO red before CPU red
        → scale workers OR shed load OR delay cron materialization
In the interview: Pick one scene. Tell what users felt, which metric lied, and what you would ship: idempotency keys, jitter, a lease reaper or gated DLQ replay.
Bottlenecks and tradeoffs
Those stories all trace back to a small number of choices where you cannot have both things you want. Interviewers listen for whether you can name the tension, say what breaks, and pick a side on purpose. Here are the ones that matter most for a job scheduler.
Simplicity vs scale (database as the queue vs external queue)
The tension — Database polling has fewer moving parts until the tick becomes the bottleneck.
What breaks — The primary melts on next_run_at scans and SKIP LOCKED contention, and dispatch lag grows.
What teams do — Start with the database as the queue, move ready work to an external queue when tick or claim contention hurts, and use an outbox for consistency.
Say in the interview — Name when you add Kafka or SQS, not “on day one by default”.
Strong timing vs queue latency
The tension — “Run exactly at T” conflicts with running jobs through a queue.
What breaks — Jobs arrive seconds or minutes late during a backlog.
What teams do — State the target as “within N seconds of T”, jitter schedules to avoid herds, and delay creating new occurrences when backlogged.
Say in the interview — An honest latency bar beats pretending to have nanosecond-exact cron on a queue.
At-least-once vs exactly-once rhetoric
The tension — Product language wants “once”, and the network gives retries.
What breaks — Duplicate side effects when handlers are not idempotent.
What teams do — Idempotency keys, dedupe tables, an outbox on the customer’s side, and never promising exactly-once on the wire.
Say in the interview — “Delivery attempts are at-least-once, and effects are idempotent.”
History retention cost
The tension — Detailed execution logs help debugging but cost money at about a terabyte a year.
What breaks — Storage bills climb and queries slow down.
What teams do — Archive successes, retain failures longer, and partition by time.
If you remember one thing: Every tradeoff ties back to tick cost, queue age or duplicate effects.
Interview tips
You now have a full design and the tradeoffs behind it, so the last thing to practice is defending it when the interviewer pushes back. These five are the pushes that come up most after you finish the design.
At-least-once vs exactly-once
In the room
You might say: “The scheduler guarantees each job runs exactly once.”
Interview Push: “A worker crashes after the customer’s server answered 200 but before the worker acknowledged. What happens?”
Land here: On the network you cannot honestly promise that a timed-out call ran zero times or one time, so delivery is at-least-once. The lease expires, another worker claims the job, and the customer’s server receives it a second time. Exactly-once effects come from idempotent handlers, dedupe tables keyed by
job_id, or external systems that treat a duplicate POST as success. Say that before they push on crashes: leases limit duplicate attempts, and idempotency limits duplicate effects.
A visibility timeout with no heartbeat
In the room
You might say: “Workers pull messages from a queue such as SQS and delete the message when the work is done.”
Interview Push: “A job takes ten minutes and the message becomes visible again after thirty seconds. Do you lose the work or run it twice?”
Land here: If the queue makes the message visible again while the first worker is still running, a second worker may start the same job and duplicate the effect. Without a heartbeat extension, that window is wide open. Use a lease on the job row (
locked_until, heartbeat), or extend the message’s visibility on a timer. When the lease really expires, another worker may claim it, which is a duplicate unless the handler is safe. That is a visibility timeout done correctly.
Repeating schedule on a leader failover
In the room
You might say: “One cron daemon runs on a virtual machine and starts the jobs.”
Interview Push: “The leader dies at :00 and a backup starts. Does midnight billing fire twice?”
Land here: Relying on “only one scheduler is alive” fails exactly during a failover. Use a unique
(cron_id, occurrence_ts)on creation, or fencing tokens so a stale leader cannot create work. Mention a deterministic job id for each scheduled minute. Failover drills at schedule boundaries are production reality, because that is exactly when the bug appears.
Clock skew across scheduler machines
In the room
You might say: “A job runs when the machine’s
now()passes its time T.”Interview Push: “The clocks on fifty scheduler machines drift apart. Are jobs early or late?”
Land here: If every machine trusts its own wall clock, some jobs start early and others late whenever clocks drift. Trust the stored
next_run_at, compared against the database’s time or a single leader’s clock, instead. Admit that schedules are “within N seconds”, not perfect to the nanosecond.
Catching up after downtime
In the room
You might say: “After an outage, we run everything that was due while we were down.”
Interview Push: “You were offline for six hours. Millions of jobs are due at once. What happens?”
Land here: Releasing every overdue job at once recreates the top-of-hour stampede. Rate-limit the catch-up, use separate priority lanes for new work and for the backlog, and spread the starts with jitter. State that some jobs are no longer worth running, such as an old reminder, and let owners mark those as skippable.
Red flags to avoid without correcting yourself: “Exactly-once HTTP callbacks”, fire-and-forget with no lease, cron at :00 without jitter, “replay all” on the DLQ with no gate.
After each push, close with one real mechanism you would build, such as a lease, a dedupe key, a DLQ or jitter, and not “we will scale the workers”.
What should stick
After working through the requirements, the decisions and the depth sections, you should be able to explain:
- When versus who — The durable store decides when, workers decide nothing and only claim and run with leases and heartbeats.
- At-least-once delivery, idempotent effects — Retries are normal, and the job’s own code must make a repeat harmless.
- Occurrence dedupe on failover — A unique
(cron_id, occurrence_ts)or fencing stops two leaders from firing midnight billing. - Leases for stuck work — A worker dies, the lease expires and another worker retries; a job that keeps failing goes to the DLQ.
- Measure queue age — The depth of the queue and the age of its oldest job beat CPU as a measure of user-visible lateness.
Tell it in the room: “Jobs are saved with next_run_at. A tick reads a bounded batch of due rows and creates ready work, once per occurrence. Workers claim with a lease and heartbeat, call the customer’s webhook, and acknowledge or retry with backoff. Repeating schedules use jitter. Handlers must be idempotent because delivery is at-least-once.”
Quick check before a mock: (1) What does the lease protect against? (2) Why is exactly-once wrong on the wire? (3) What stops midnight from firing twice? → (1) two workers owning one job, and a dead worker’s job staying stuck (2) a timed-out call may or may not have been processed, so a retry can repeat it (3) a unique occurrence key plus a fencing token.
Practice next: Open Design a Job Scheduler on Practice System Design and run a timed attempt using clarifying questions and one job’s story, without peeking until you have a draft on the board.
Key Takeaways
- Store every job durably with its next run time and answer 202 before any worker runs it, so a restart cannot lose a promise.
- Find due jobs with an index on the next run time and a bounded batch per tick, so the cost depends on what is due and not on how many jobs exist.
- Claim a job with an expiring lease and heartbeats, so a dead worker’s job becomes available again and two live workers never own the same attempt.
- Promise at-least-once delivery and make the job’s effects idempotent, because exactly-once cannot be guaranteed on a network.
- Give each occurrence of a repeating schedule a unique key and a fencing token, and add jitter so the top of the hour is not a stampede.
- Retry with growing gaps up to a maximum, then park the job in a dead-letter queue and replay it only a little at a time.
- Watch the age of the oldest runnable job, tick duration, lease expiries and DLQ ingress, not only worker CPU.
Related Topics
- Rate Limiter System Design — Admission control and fair-share patterns for enqueue APIs
- Notification Service System Design — Async delivery, retries, and idempotent sends after job completion
- Distributed Cache System Design — Hot metadata, coordination, and lease-like TTL patterns
- Job Scheduler practice workspace — Whiteboard this problem with interviewer prompts
Quick revision notes
The problem in your own words. A job scheduler decides when each piece of background work starts and which worker runs it. The hard part is that machines die and networks fail, so the same job can run twice, never run, or stay stuck, while thousands of jobs can become due in the same second.
The design in one breath. Every job is saved with its next run time, and the client is told “accepted”. A tick reads a small batch of due rows through an index and creates ready work, once per occurrence. Workers pull a job and claim it with an expiring lease, sending heartbeats while it runs. They call the customer’s system with the job id, attempt and lease version, and the customer ignores duplicates. Success is acknowledged, a failure is retried with growing gaps, and a job that keeps failing goes to the dead-letter queue for a person.
The choices you must be able to defend. The database as the queue first, and a separate queue when the tick or the claims make the primary hot. A lease with heartbeats and not a lock that never expires. Idempotent handlers and not a promise of exactly-once. A unique occurrence key plus a fencing token for repeating schedules. Jitter for the top of the hour and separate lanes so urgent work is not stuck behind bulk work.
The numbers worth remembering. About 115 attempts a second on average from 10 million a day, but 50,000 jobs due at once at the top of the hour, which jitter over five minutes turns into about 170 a second. About a terabyte of history a year, and about 170 heartbeat writes a second for 10,000 long jobs at a 60-second interval, though a 5-second interval would be about 2,000 (all estimates).
The mistakes that cost points. Fire-and-forget dispatch with no lease, promising exactly-once on the wire, schedules at :00 with no jitter, no unique key for occurrences, a single line for all jobs, replaying the whole DLQ at once, and watching CPU instead of the age of the oldest job.
Frequently asked follow-ups
- How do you scale cron without a thundering herd at :00?
- Can you guarantee exactly-once execution?
- How do priority queues work without starving low-priority work forever?
- What happens when a worker crashes mid-job?
- How is this different from Airflow or Kubernetes CronJob?
Deep-dive questions and strong answer outlines
What is the high-level architecture?
Clients POST jobs to an API that persists metadata in a durable store. A scheduler leader (or sharded schedulers) runs a tick loop: query rows where next_run_at is due, enqueue to a ready queue or claim directly. Workers pull, claim with a lease (locked_until, worker_id), extend the lease via heartbeat for long jobs, execute the payload, then ack or retry with backoff. Failed poison jobs land in a DLQ after max attempts.
How do you handle cron at scale?
Store next_run_at per cron job; materialize each occurrence with a dedupe key (cron_id, occurrence_ts) unique constraint so leader failover does not double-fire. Add jitter within a window so millions of jobs do not all enqueue at :00. Shard schedulers by tenant or hash when one leader cannot scan fast enough.
How do retries and DLQ work?
On failure, increment attempt count, apply exponential backoff with a cap, and re-enqueue. After max attempts, move to DLQ with error blob and alert on-call. DLQ replay is manual or gated — not an automatic loop that floods downstream again.
Can you guarantee exactly-once execution?
Not on the wire — queues and HTTP callbacks are at-least-once. Guarantee effectively-once business effects via idempotency keys, dedupe tables on (job_id, logical effect), or outbox pattern. Say that out loud before the interviewer pushes on worker crash after callback returned 200.
How do long-running jobs differ from short tasks?
Separate queue or concurrency pool; longer lease TTL; heartbeat to extend locked_until while work continues; optional checkpoint or split into subtasks. Short jobs use tight leases; long jobs must not lose the lease at 30 seconds while still running for ten minutes.
AI feedback on your design
After a practice session, InterviewCrafted summarizes strengths, gaps, and interviewer-style expectations—similar to a written debrief. See a static example report, then practice this problem to get feedback on your own answer.
FAQs
Q: Is Kubernetes CronJob enough for this interview?
A: K8s CronJob is a useful subset for one cluster, but the interview usually wants a distributed scheduler: durable job store, priority, retries, DLQ, multi-tenant fairness, and what happens when the cron leader fails over. Mention K8s as a deployment target for workers, not as the whole design.
Q: How does this relate to DAG workflow engines like Airflow?
A: Tools like Airflow sit above a simple scheduler when you need graphs of jobs that wait on each other, screens to re-run old ranges of time, and libraries of ready-made steps. Park that full orchestration out of scope unless asked. If you mention dependencies at all, say a child becomes ready when its parents finish, and keep the core answer on start, claim, retry, and safe repeats.
Q: How do delayed or scheduled-one-shot jobs work?
A: Save the next run time on the job row. A small scheduler loop wakes up regularly and picks rows whose time has arrived. If ready work sits in a separate queue, a delay or visibility timeout does the same “run after T” job. The create call answers as soon as the job is saved (usually HTTP 202), and the actual run happens later.
Q: What should I monitor in production?
A: How many jobs are waiting and how long the oldest one has waited (that is the delay people feel), how long each scheduler tick takes, how often leases expire without success, how often jobs retry or land in the dead-letter holding area, how late due schedules are at becoming ready, and whether one team is using more than its fair share — not only how busy the worker machines look.
Q: DB-as-queue or Kafka/SQS — which do I pick?
A: Letting workers claim ready rows from the database works at moderate scale and keeps one system of record. A separate queue smooths bursts, brings a built-in retry and dead-letter path, and lets the scheduler tick and the workers move at different speeds. Start with the database; move ready work to a queue when the tick or the claims start fighting for the same primary, not on day one by default.
Q: How do I practice this problem on InterviewCrafted?
A: Use the interactive whiteboard at /practice-system-design/design-job-scheduler — walk through leases, cron jitter, and idempotency under interviewer prompts.
Practice interactively
Open the practice session to use the canvas and stages, then review AI feedback.