System design interview guide
Facebook Feed System Design
Picture opening a social app after lunch to see what your friends have been up to. A friend posted ten minutes ago, yet the list you scroll, called the home feed, still looks like yesterday. The post did get saved, but the app was still busy getting it in front of everyone who follows your friend, and a famous page with tens of millions of followers can keep that work busy for a long time. A good answer explains how a new post reaches its followers quickly without making the person who posted wait, and what changes for accounts with huge followings.
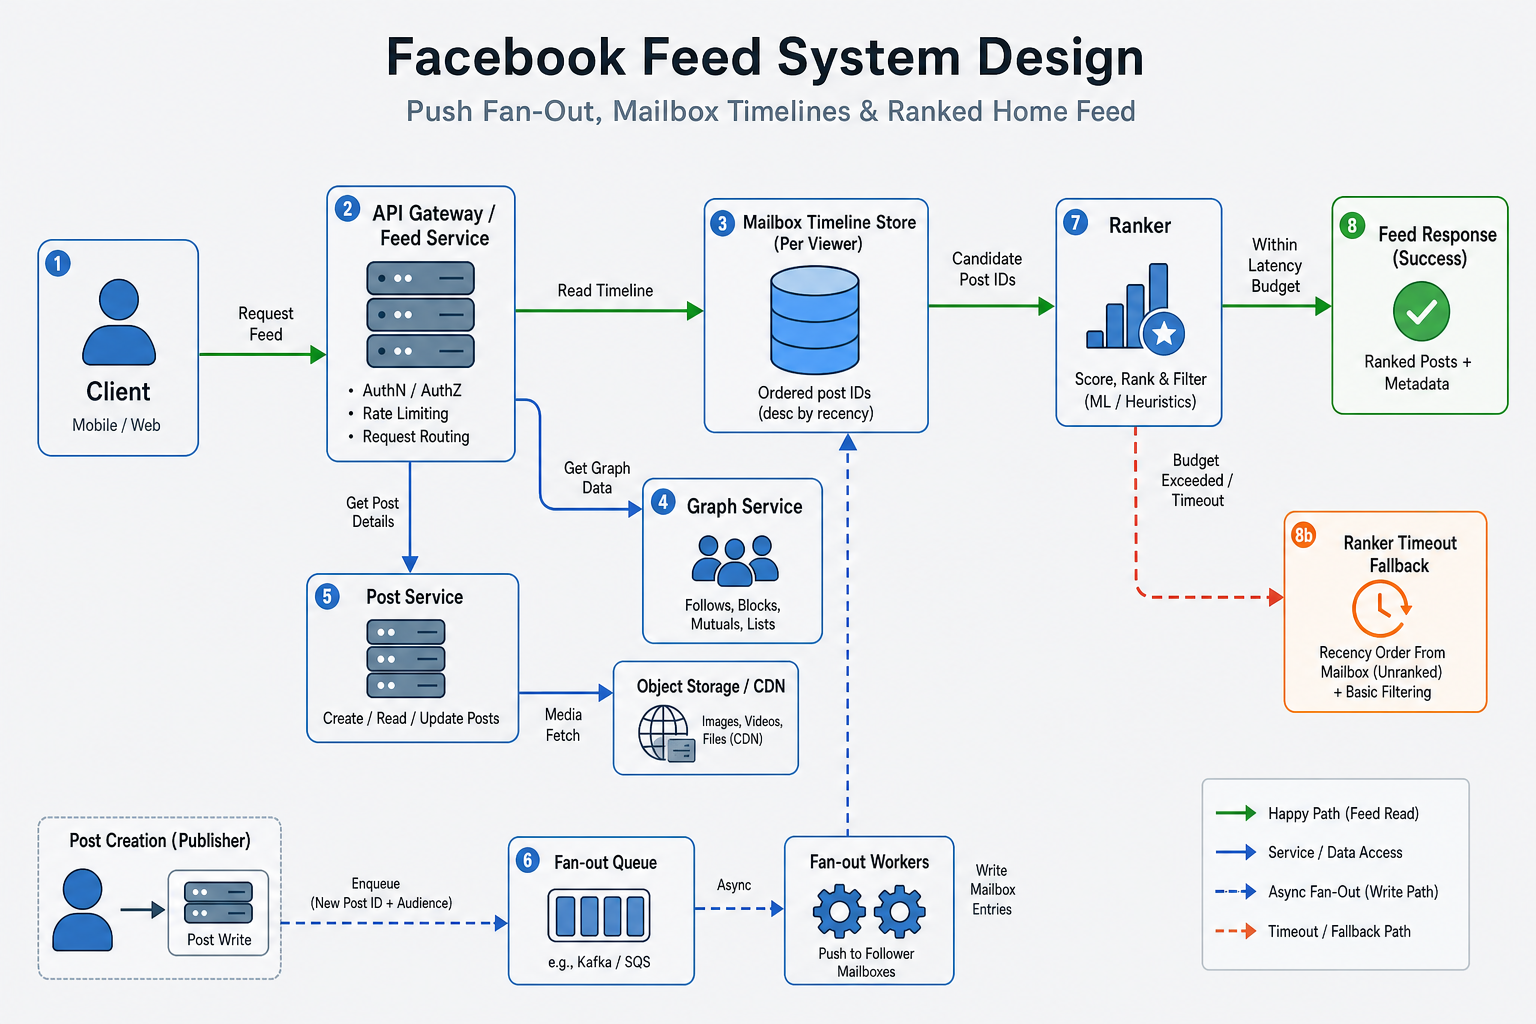
Problem statement
You're designing the home feed of a social network like Facebook: the list of posts, from the people and pages someone follows, that they scroll through after opening the app. It can be ordered by what the system thinks they will enjoy, or simply by newest first. It is shown one page at a time, and it has to feel fast. Functionally the system must let people publish a post, follow and unfollow, scroll home one page at a time, optionally like or comment, choose ranked or newest-first order, and block or mute. Non-functionally, most common scrolls should finish in under about 300 milliseconds, the feed should stay available, and a saved post must stay saved—while a new post may take a few seconds to show up for followers. Scale sits at hundreds of millions of people active each day, with scrolls far outnumbering posts, and a few accounts whose follower counts are so large that copying each post to every follower becomes a cost and reliability incident. What interviewers reward: a clear rule for ordinary versus very large accounts; personal lists of post ids kept separate from post bodies; a capped set of candidates and a time limit on scoring; continuation tokens with honest rare duplicates or skips; and degrading the ordering—not showing a blank feed—when a dependency fails.
Introduction
The problem: a friend posted ten minutes ago
Imagine you finish lunch and open a social app to see what your friends have been up to. One of them posted a photo ten minutes ago, and you know because they just texted you about it. But the list of posts you scroll through, called your home feed, still shows yesterday at the top. You pull down to refresh and nothing changes. Your friend’s post did go through, and if you open their profile you can see it sitting there. Your own list is simply behind.
Nothing here is broken in the way a crashed page is broken, and that is what makes this problem interesting. The app has two jobs that move at different speeds. One job is to accept and safely save a post. The other is to get that post in front of everyone who follows its author, in a sensible order, quickly enough that the app feels live. A system can be fast at the first job and slow at the second, and the person who posted never notices.
Now add size. Hundreds of millions of people open the app every day, and each of them scrolls many times, while only a small share of them post anything. A few accounts, such as a famous singer’s page, have tens of millions of followers. Every one of those followers wants to see the new post soon after it goes up, at the same moment everybody else is scrolling too.
Why teams bother with a good home feed
Almost nobody scrolls a social app by visiting each friend’s page one by one. The home feed is the front door of the whole product, and the people who build it care about it for several concrete reasons.
People come back when it feels alive. If the feed shows fresh and interesting posts, people open the app again tomorrow. If it feels stale, they stop checking, and for a social product that is the beginning of the end.
People who post need to be seen. Someone who shares a photo and gets no reaction for an hour learns that posting is pointless. The feed is the promise that what you post will reach the people who follow you.
The feed is where most of the money and traffic is. Opening the feed is the single most common action in the product, and everything else, including ads, hangs off it. Every extra fraction of a second and every extra stored row gets multiplied by hundreds of millions of people.
Trust and safety show up here first. If you blocked someone and their post still appears in your feed, you stop trusting the product. Rules about who may see what must hold even when the rest of the system is running behind.
What problem are we solving?
Whenever a person opens the app, the system has to produce one page of posts from the accounts they follow, in a sensible order, in a fraction of a second. When they keep scrolling, it has to produce the next page, and the next. The inputs are who is asking, whom they follow, and which posts exist. The output is a page of posts plus some way to ask for the page after it.
Success has four parts. The page appears fast. A new post from someone you follow shows up soon, even if not instantly. People you have blocked never show up. And when some part of the system is slow, the person still sees a feed rather than a spinner or a blank screen.
We will not guess at the shape of the solution yet. First we need to be clear about what the system must do and how well it must do it, so that each design choice later has a reason behind it. This page is the interview deep dive in the system design interview guides hub, and it follows the order you would actually think through the problem: requirements first, then size, then decisions, then the picture those decisions make.
How to approach
We just framed what success looks like for a home feed. In the interview you still do not start by drawing boxes. You turn a short, vague prompt such as “design the Facebook feed” into a contract: what the feed contains, what the system must do, how well it must do it, and what you will leave out. Only then do you size the problem, make the design decisions one at a time, and draw the result. The list below is the order this page follows.
How to design a home feed in an interview
- Clarify the problem: what counts as the home feed, whether it is ranked, how fresh it must be, whether very large accounts exist, how big the system is, and how exact the order and the privacy rules must be.
- Write the functional requirements (what the system does) and the non-functional requirements (how fast, how big, how reliable).
- Estimate the size: how many people scroll, how many post, and how many followers one post has to reach.
- Make the design decisions in order: when the work of building a list happens, what the list stores, what to do about very large accounts, when a post counts as published, how much work one scroll may do, what happens when ordering is slow, how the next page works, and how blocks take effect.
- Draw the picture those decisions produce, then walk one publish and one scroll through it.
- Go deeper where the interviewer pushes: the very large account, the ranker, pagination, hot posts, and one production failure.
Clarifying questions (say these in the room)
The prompt in a real interview is only a few words. Before you design anything, ask questions until the problem is clear. Each answer below changes the design, which is why it is worth asking.
You: “When you say the feed, do you mean only the home timeline made from people and Pages I follow, or should I also mix in Groups posts and ads in this round?”
Interviewer: “Just home from follows. Ads and Groups are out of scope.”
That answer tells you what the candidates for a page are: posts written by accounts the viewer follows. Groups and ads come from different sources, such as group membership or an ad auction, and each would be a system of its own. You can say “ads inject candidates later” and move on.
You: “Should home be ranked, like a ‘Top stories’ view, or is a newest-first list enough for this interview?”
Interviewer: “Ranked home, with a fallback to newest-first if ranking is slow.”
Ranking means a separate step scores the posts, and a step that scores posts can be slow or can fail. So the design owes a time limit for that step and a plain newest-first answer for the moments when it is late.
You: “Is it OK if friends see a new post a few seconds after it is published, as long as blocks and ‘don’t show me this’ rules stay correct?”
Interviewer: “A short delay for friends is fine; blocks must not wait.”
This is the permission that makes the whole design possible. If a few seconds of delay is fine, the work of spreading a post can happen after the author gets their answer. The privacy rules cannot be delayed like that, so they will have to be checked at the moment someone reads.
You: “Should accounts with tens of millions of followers be treated as a special case?”
Interviewer: “Yes, call out celebrities explicitly.”
You now owe the room a clear rule for very large accounts, because a rule that works for a friend with two hundred followers may not work for a page with fifty million.
You: “Roughly how many people use this per day, and how many times does each open the feed?”
Interviewer: “Assume a few hundred million people a day, a handful of feed opens each, and a few hundred million new posts a day.”
Those numbers feed the capacity estimate in the next section. They also tell you early that scrolling is far more common than posting, so the scroll is where speed matters most.
You: “How exact does the feed have to be? If two people see the same list in a slightly different order, or a post shows up twice while scrolling, is that acceptable?”
Interviewer: “Best effort is fine for order and the odd repeat. Blocks and deletes must be exact.”
That answer decides how honest you can be about moving order later, and it separates what may be approximate from what may not.
You: “I’ll keep the ads auction, the training of the ranking model, and Reels or Stories out of scope so we can focus on publishing, spreading posts, reading a page, and what happens when ranking is slow. Does that match what you want?”
Interviewer: “Yes, home feed at scale.”
Saying this early stops the round from drifting into adjacent products. If the interviewer later asks about store brands, queue products or how a model is trained, you do not need to answer yet. Park those until the design decisions, where each one has a natural place.
Functional requirements
Functional requirements describe what the system does. From the answers above, the home feed must:
- Let people publish a post. The author writes text, perhaps with photos or video, and the system saves it and confirms quickly. A confirmed post must never be lost.
- Let people follow and unfollow accounts. The accounts someone follows decide what can appear in their feed, so this list drives everything else.
- Show a home feed one page at a time. When a person opens the app they get a page of posts from the accounts they follow, and when they keep scrolling they get the next page.
- Offer two orders. A top view orders posts by how interesting the system thinks they are, and a recent view orders them by newest first. Recent is also what the person sees when ranking is unavailable.
- Let people block and mute. Someone you have blocked must not appear in your feed, even if their post was already on its way to you.
- Support likes and comments in a thin way. They show up next to a post, but we do not design them in depth here.
- Work for very large accounts. A page with tens of millions of followers must be able to post without hurting everyone else’s feed.
Non-functional requirements
Non-functional requirements describe how well the system must do its job. They are the numbers and promises that shape the design.
- Speed. Most home scrolls should finish in under about 300 milliseconds at the 95th percentile (p95: 95 of every 100 scrolls finish at least this fast). This is the most common action in the product, so it has to feel instant.
- Availability. The feed must stay up almost all of the time. When a part of the system is slow or broken, the person should still get a feed, possibly in a simpler order, instead of an error.
- Freshness. A new post may take a few seconds to appear for followers. We are not promising that everyone sees it at the same instant.
- Durability. Once the system tells an author the post was accepted, the post stays saved even if machines fail.
- Scale. Hundreds of millions of people a day, hundreds of millions of posts a day, and reads far larger than writes. The work done for one scroll must stay small no matter how many accounts a person follows.
- Privacy correctness. Blocks and deleted posts must be respected on every read, even when other parts of the system are still catching up.
- Visibility. The team must be able to tell whether people are actually seeing fresh feeds, not only whether posts are being accepted.
Out of scope (and why you park these)
Write a short out-of-scope list on the board so the interviewer sees you can bound the problem.
The advertising auction and billing. Ads change ranking and money flows, but they take the interview away from spreading posts and reading a page. You can say that ads add extra candidates later without designing the auction.
Training the ranking model. You need the interface that serves it: candidates go in, scores come out, and there is a time limit. Building the data pipelines that train a model is a different interview.
Groups, Stories, Reels and Marketplace as full products. Each has its own way of choosing and ordering content. Mention them only if the interviewer widens the scope.
Strongly consistent worldwide visibility the moment someone posts. A home feed accepts a short lag. If you promise that every follower on every continent sees a post at the same instant, you have invented a much harder problem than the one in the room.
That is the requirements stage. If you want to practice it before reading on, try the requirements stage on Practice System Design (about 5–10 minutes), then come back for the sizing and the decisions.
Minute pacing (about 45–60 minutes)
| Minutes | Focus |
|---|---|
| 0–5 | Clarify home vs ranking, freshness, very large accounts, scale and exactness; write functional and non-functional requirements; agree out of scope |
| 5–12 | Capacity: reads against writes, followers per post, and one very large account |
| 12–28 | The design decisions, then the boxes and one publish and one scroll |
| 28–42 | The deep dive: large accounts, one page read, ranker timeout, cursor, blocks |
| 42–52 | Failure and one production story |
| 52–60 | Questions, and one tradeoff in depth |
In the room (how you open): “I’d start by agreeing what the feed is. I’ll ask whether it is only posts from people and Pages you follow, whether it is ranked, how fresh it has to be, whether very large accounts exist, and how big the system is. I’ll write the requirements on the board, split into what the system does and how well it does it, and agree what is out of scope. Then I’ll size the problem and make the design decisions one at a time, so every box I draw has a reason.”
If you remember one thing: Ask first, write the requirements down, and only then design. Tell one publish story and one scroll story before you name any storage product.
Capacity estimation
Now that the requirements are clear, the next step is to find out how big the problem is, because the size decides what kinds of shortcuts we can afford. We are not trying to be exact here. We want just enough numbers to show where the work piles up. The figures below are rough estimates to say out loud and tune in the room.
| Dimension | Rough scale (estimate) | What this means for your design |
|---|---|---|
| Daily active people | A few hundred million, say 300M | Home reads dominate; cache and shard aggressively |
| Feed opens | About 10 per person per day, so about 3 billion a day, or roughly 35k a second on average and 100k a second at peak | The scroll is the hot path and has to be cheap |
| New posts | About 300M a day, so roughly 3.5k a second on average and 10k at peak | Writes are modest next to reads |
| Followers per author | Highly skewed: most have hundreds, a few have tens of millions | The few large accounts dominate cost |
| Copying one post to every follower | At an average of 200 followers, 300M × 200 = 60 billion list writes a day, about 700k a second | Even ordinary authors add up to a very large write load |
| One account with 50M followers | 50M list writes for one post | At 500k writes a second set aside for it, that is still about 100 seconds of work for one click |
| Size of one viewer’s list | About 500 entries × ~24 bytes ≈ 12 KB | For 500M active viewers, roughly 6 TB before replicas |
| Page size and candidates | Tens of posts per page, a few hundred candidates considered | Bound the candidates before ordering; never score everything a person follows |
| Time budget for one scroll | Under about 300 ms p95: roughly 20 ms for the list, 20 ms for block checks, 40 ms to load posts, up to about 100 ms for ranking, the rest for the network | Ranking cannot be allowed to take the whole budget |
What the numbers imply
- Reads dominate. Roughly ten feed opens for every post at the page level, and more once you count scrolling further down. Anything we can do once at publish time instead of on every scroll is worth a lot.
- Ordinary copying is already big. Even without a famous account, copying every post to every follower’s list is hundreds of thousands of writes a second. That is why the lists must be split across many machines, and why you may choose not to write to people who have not opened the app for months.
- One large account is a special problem. Fifty million list writes for one post cannot finish fast enough to feel live, and while that work is running it delays everybody else’s posts waiting behind it.
- Storage is large but fine. A few terabytes of lists is easy for a sharded store. Storing whole posts in every list would be a thousand times larger.
- Bound the work per scroll. The budget of 300 ms leaves no room for looking at everything someone follows. Say “a few hundred candidates” out loud.
Checkpoint: Why does one post from a 50-million-follower account break the simple approach, even with a fast queue?
If you remember one thing: The numbers exist to show skew: reads dominate, and a handful of huge accounts can break any approach that treats every author the same.
Design decisions
We now know what the system must do, how fast it must be, and roughly how big it is. Now we choose. Each decision below answers one question that the requirements raised, and each one rules out an easier idea that would not survive those requirements. Read them in order, because every decision builds on the one before it.
Decision 1: When do we build a person’s list, at publish time or at scroll time?
The requirements said a scroll must finish in about 300 milliseconds, and that scrolls are far more common than posts. The simplest idea is to do nothing in advance. When someone opens the app, look up the recent posts of every account they follow, merge them, and sort them. This is called pulling on read, and for a small product it is exactly right.
It breaks against the speed and scale requirements. A person who follows 2,000 accounts would need 2,000 lookups for one scroll, inside a 300 ms budget. With about 100,000 scrolls a second at peak, that is hundreds of millions of lookups a second, repeated almost identically every time the same person scrolls again.
The other direction is to do the work once, at publish time. When a post is saved, the system writes a small note about it into the personal list of each follower, and a scroll then needs one lookup in one list. This is called pushing, or fan-out on write. Because scrolls are many times more common than posts, paying once at publish is much cheaper than paying on every scroll, so we choose to push for the common case. The price is that the cost of a publish grows with the number of followers, and the next decision is about what exactly we write into those lists.
Decision 2: What does each person’s list actually store?
The simplest idea is to copy the whole post into every follower’s list, so that a scroll just reads the list. It fails quickly. A post with a few hundred characters and a photo link, copied to 200 followers, is 200 copies to store. When the author edits or deletes the post, every copy has to be found and changed, and for a private post a missed copy is a privacy bug.
So each list stores only a pointer: the id of the post, the id of the author, and a time or score used for ordering. The text, the photo links and the author’s name live once, in a separate post store, and a scroll fetches them for just the handful of ids on the page. In this page we call that personal list of ids a mailbox, like an inbox that holds notes saying “post 8421 by author 77 arrived at 12:41” instead of the full letters. Two boxes on the board, one of ordered ids and one of bodies, is one of the most important things to draw.
Decision 3: What do we do for accounts with tens of millions of followers?
Decision 1 said we push a note to every follower. The simplest idea is to apply that rule to everyone, including a page with 50 million followers. Then one post means 50 million writes. That is about 100 seconds of work even if the system gives it half a million writes per second, and while the queue is busy with it, other people’s posts wait behind it, so friends’ feeds go stale for minutes. It also costs real money, since every row is stored and indexed.
There are three ways out.
- Pull for everyone. We already rejected this in Decision 1, because it breaks the speed requirement for people who follow many accounts.
- Push only to people who are active right now. This cuts the work, but it still writes millions of rows, and people who come back later find their lists missing posts.
- Do not push at all for very large accounts, and merge their posts when someone scrolls. The big account’s recent posts are kept in one short list indexed by author. When a viewer scrolls, the system reads their mailbox and also the recent posts of the few big accounts they follow, and blends them. One post costs one write instead of 50 million, and the extra work lands on the scroll, which is bounded because a person follows only a handful of huge accounts.
The third option combines the first two, so it is called a hybrid policy: push for ordinary authors, merge on read for very large ones, and optionally push to recently active viewers in between. Where the line sits matters less than saying that a rule exists and naming what it protects: queue depth, storage, and the blast radius of one post. The cost you accept is extra work on every scroll for people who follow big accounts, which is why that work must be capped.
Decision 4: When does the author get told the post worked?
The simplest idea is to say “posted” only after the post has been written into every follower’s mailbox. It is easy to reason about, since success means everyone has it. It fails the speed and availability requirements. An ordinary author with 5,000 followers would wait on 5,000 writes, and a failure on any one of them would make the whole post fail.
So the author is told yes as soon as the post itself is durable, which means saved in a way that survives a machine failing, such as copied to more than one machine. The system then puts a job onto a queue, and background workers write the notes into the mailboxes at their own pace. Because queues generally promise to deliver a job at least once, a job can run twice after a crash. So each mailbox write is keyed by the pair of viewer id and post id, and writing the same pair twice does nothing the second time. Search indexing, notifications and link previews follow after the post exists too, never in front of the answer to the author.
The consequence is that there are now two clocks: when the author sees success, and when a follower sees the post. A good answer says so out loud and measures both.
Decision 5: How much work may one scroll do?
The simplest idea is to take everything the person could possibly see, score it all, and return the best. With people following thousands of accounts and posting every day, “everything” is unbounded, and the work per scroll would grow with how active someone’s network is.
The requirements call for a bounded scroll, so we decide the shape of the work in advance. The system reads the head of the viewer’s mailbox, adds the recent posts of the few big accounts they follow, and stops at a fixed cap of a few hundred candidate ids. It then loads the bodies for only those ids, in one batch, throws away anything blocked or deleted, and returns one page. The cap is a product choice: a higher cap finds better posts and costs more time.
Decision 6: What happens if putting the posts in order is slow?
The requirements say the feed must stay up and answer in 300 ms. The step that scores the candidates is a separate service, often backed by a machine-learning model, and it is the least predictable part of the path. The simplest idea is to call it and wait for the answer. But if it slows down after a release, every scroll waits, the machines that serve the feed run out of free threads, and unrelated pages start to feel slow too.
So the ranking step gets a deadline, a fixed number of milliseconds, say 100 out of the 300. If it does not answer in time, the feed returns the candidates in newest-first order, or the last good order it remembers. A circuit breaker (a switch that stops calling a service that keeps failing, like a fuse) skips the ranker entirely for a short while, and a kill switch lets the team turn off a heavy model without a deploy. The product promise becomes “you always get a feed, and usually a well-ordered one,” which is better than a perfect order that sometimes never arrives.
Decision 7: How does the next page work when the order moves?
The simplest idea for “page two” is to skip the first 20 results and take the next 20, the familiar offset and limit. It breaks because the list is alive. Between the first request and the second, new posts arrive and scores change, so the item that was number 21 may now be number 23. With an offset you either see the same post twice or miss one completely.
Instead, the response to every page includes a cursor, an opaque string the client sends back to say where it stopped. It encodes the last score and post id that was shown, so the next page continues strictly after that position. The client also skips any post it has already displayed. We say honestly that this is best effort: after scores shift, a post may rarely be missed, and no real system promises a perfectly stable order while the list moves.
Decision 8: How do blocks, unfollows and deletes take effect?
The simplest idea is to remove the affected rows from mailboxes the moment something changes. For one person unfollowing one account that works, because it touches only that person’s list. But a post that is deleted or made private after it was pushed touches the mailboxes of every follower, and a safety rule cannot wait until a background job finishes cleaning hundreds of millions of lists.
So the rule is checked at read time. Every scroll loads the viewer’s block and mute list from a cache that must be fresh, and the post bodies tell us whether a post is deleted or no longer visible. Anything that fails these checks is dropped before the page is built. The mailbox cleanup, such as removing old unfollowed rows, happens later in the background or simply by letting old entries expire. The cost is that a few stale ids may be read and thrown away, which is far cheaper than getting a privacy rule wrong.
Putting the decisions together
Taken together, the eight decisions are the design. A publish saves the post once and tells the author it worked. Background workers push the post’s id into follower mailboxes, except for very large authors, whose recent posts are kept by author. A scroll reads a capped set of ids from the mailbox, adds the big authors’ recent posts, loads the bodies in one batch, drops anything blocked or deleted, asks the ranker for an order under a deadline, and returns a page and a cursor.
In the room (a fuller opening you can actually say): “I’d say there are two jobs that move at different speeds, publishing and scrolling, and that scrolling is far more common. So I’d do the heavy work once, at publish time. The post is saved first and the author gets an answer straight away. Then background workers write a small note containing just the post id into each follower’s personal list, and those writes are safe to repeat. For very large accounts I would not write millions of notes. I’d keep their recent posts by author and merge them in when someone scrolls. A scroll reads a capped set of ids, loads the posts in one batch, drops anything blocked, and asks the ranker for an order with a hard deadline, falling back to newest-first if it is late. The next page uses an opaque cursor instead of an offset, because the order moves, and blocks are checked at read time so privacy never waits for background work.”
The next section draws these decisions as one picture and shows who owns what.
High-level architecture
The decisions above were made one at a time. This section puts them on one page as a picture: which boxes exist, who owns what, and how a publish and a scroll travel through them. The deeper mechanics come later, so keep this at the level of a map.
What breaks if you merge everything
Imagine one service that stores the full post in every follower’s list, ranks with no time limit, and refuses to confirm a post until every list is written. It would choke the first time a large account posted, and it would hang the front door whenever the machine-learning service slowed down. Logging every ranking feature on the live path would make the 95th-percentile time worse without teaching anyone anything in the room.
What works: ids on the timeline, bodies elsewhere
Who owns what:
- API / edge — Authentication, rate limits, and time limits on everything it calls.
- Feed service — Runs the read path: candidates, graph checks, loading bodies, ranking and the cursor. This is where the work is capped.
- Mailbox / timeline store — Ordered post ids (or score and id) for each viewer, split across machines by
user_id. - Post service + object storage + CDN — The source of truth for post metadata and for photo and video bytes. A CDN is a network of servers near users that hands out those files quickly.
- Graph service — Follow, unfollow, block and mute, cached carefully on the feed path.
- Fan-out workers — Read jobs from a queue and write notes into mailboxes where the policy says to push. Writing the same
(viewer_id, post_id)pair twice does nothing the second time, so a crashed worker can safely retry. - Ranker — The scoring service that orders a capped set of candidate posts under a hard time limit.
Large accounts on the whiteboard: For authors you do not fully push, the feed service merges recent posts by author into the candidate pool. Draw that edge, or you will have drawn only the push path and invited the follow-up you deserve.
[ Client ]
    → [ LB / API gateway ] → [ Feed svc ] → [ Mailbox store / big-author merge ]
                                 |                    ↓
                                 |              [ Ranker + timeout ]
                                 |                    ↓
                                 +-- [ Graph ]   response + cursor
                                 +-- [ Post svc ] ← media via CDN
                                 |
          [ Post create ] → durable post → [ Fan-out queue ] → workers → mailboxes
In the interview: Narrate the read path first (the time budget, the bounded candidates, the ranker deadline). Then one write (a durable post, a queue, then idempotent mailbox writes). Storage brand names come after the story makes sense.
If you remember one thing: The read path is ids → batch load → rank with a deadline, and the write path confirms before every mailbox row exists.
Core design approaches
The decisions chose a mix of two ways of building a list. This section puts the three families side by side, so you can say where each choice sits and when you would pick another.
Fan-out on write (push)
After a post is stored, the system pushes its id into each follower’s mailbox. Reads feel cheap because the heavy work already happened. The catch is that the work grows with the number of followers. The moment you say “we push to everyone,” you owe the room a large-account exception, or you have designed a machine that spends your cloud budget as a write storm.
Pull on read
At request time the system pulls recent posts from every followed account and merges them. That avoids the large-account write blast, but it can burn a lot of CPU when someone follows thousands of accounts, so real systems cap it, cache it, or mix it with push.
Hybrid (what production usually sounds like)
| Policy | When it fits | Cost you accept |
|---|---|---|
| Push to follower mailboxes | Long-tail authors (modest follower counts) | Storage and fan-out CPU on publish |
| Merge / pull recent by author | Celebrities and mega-pages | Extra work on the home read path |
| Partial push to active users | Middle tier or “online now” optimization | Stale mailboxes for inactive viewers |
Push for the long tail—the many ordinary authors with modest follower counts. For mega-followed authors, do not write a row for every follower edge. The exact threshold matters less than saying there is a policy and naming the cost driver (how deep the work queue grows, how much you store, and how far one post’s blast spreads).
If you remember one thing: Hybrid is the real answer, because pure push or pure pull alone fails at this scale.
Data model
The mailboxes and the post store need real shapes, so the next question is what exactly gets stored. Keep three ideas separate: what each viewer scrolls, what a post is, and who can see whom.
Mailbox / timeline (per viewer)
| Field / concept | Why it exists |
|---|---|
viewer_id | Which person’s list this row belongs to; also how you split lists across machines |
post_id | Pointer into the post store, not the full body |
score or created_at | Ordering hint for newest-first or last known score |
author_id | Helps the big-author merge and filtering |
Unique on (viewer_id, post_id) | Writing the same pair twice must not create a duplicate row after a retry |
Beside the per-viewer mailboxes, large accounts get a short author recent list: the last few hundred post ids by author, which the scroll merges in.
Posts and media
| Concept | Store | Note |
|---|---|---|
| Post metadata | Post service / DB | Author, text, privacy, timestamps, media keys |
| Media bytes | Object storage + CDN | Upload before or beside create; the feed path only carries URLs or ids |
| Author profile cache | Cache / profile svc | Safe to be slightly stale for display names |
Graph
| Edge | Hot-path rule |
|---|---|
| Follow | Drives push membership and the set of big authors to merge |
| Block / mute | Must filter on read even if mailboxes lag |
| Unfollow | May purge asynchronously; filter until the purge completes |
Interview land: Draw “mailbox = ordered ids” and “post store = bodies” as two boxes. One database that stores full posts in every follower row is the anti-pattern.
Detailed design
We now know what is stored and where, so we can put the pieces in motion. This section tells one publish and one scroll as a story, the way an outage retro would, and then shows the same thing from the caller’s side in the API. Read it once as a story. The mechanics and the follow-up questions come in the deep dive right after it.
Write path
Start with the person who taps Share. Photos and video usually upload first into object storage—a durable file store for large blobs—or they upload in parallel while the post service writes the small facts about the post: who wrote it, the text, who may see it, media ids, and timestamps. The create call returns success once those facts are safely saved. It does not wait until every follower’s personal list has a new row, because that wait is how a post from a large account times out for the author.
Copying the post id into follower lists then runs in the background. Workers write where the policy says to push, and each write is keyed so a retry cannot create a duplicate row. Search indexing, notifications, and link previews can trail afterward. If you put those on the path that answers the author, you miss the speed target and still sometimes generate the wrong preview image.
Read path
Scrolling home has a tighter time limit than publishing, because it happens far more often. The feed service loads a capped set of candidate post ids for this viewer—usually from their personal list, plus any merge of big authors they follow. It fetches the post bodies and author cards for those ids only, in one batch. It applies block and hard safety filters here even if an old id still sits in a list. Then it asks for scores under a hard time limit, and if the scoring service is late it returns a newest-first or last-good page instead of hanging the app. Finally it attaches an opaque cursor—a continuation string the client sends back—so the next page can continue even if ranks move between requests.
If your whiteboard answer stops at “we call the ML service,” the follow-up will be what happens when that service is slow. Strong answers already have the deadline and the fallback in the read story.
API design: what clients send and what operators change
An API here means the method names clients and services call, plus the answers they get back. A feed is mostly a read surface, so this subsection covers three things: the calls inside the system, what the phone sends and receives, and the small set of controls operators use. The paths below are an illustrative REST-style surface (GraphQL is fine if you name batching and field cost, because feeds are where naive graphs hurt).
POST   /v1/posts
GET    /v1/me/home
GET    /v1/posts/{post_id}
POST   /v1/users/{user_id}/follow
DELETE /v1/users/{user_id}/follow
The internal calls. Inside the system, the feed service makes three calls on every scroll: one to the mailbox store for the viewer’s candidate ids, one batch call to the post service for those ids, and one call to the ranker that carries a deadline. The deadline is part of the call, so a slow ranker is cut off instead of waited for.
GetCandidates(viewer_id, cursor, cap)  → [post_id, author_id, score]
BatchGetPosts([post_id])               → [Post]
Rank(viewer_id, candidates, deadline)  → ordered ids   (or timeout → fall back to recency)
What the client receives — GET /v1/me/home.
| Query param | Role |
|---|---|
cursor | Opaque continuation (preferred) |
limit | Page size (cap server-side, e.g. ≤ 50) |
ranking | top or recent |
session_id | Optional session snapshot for experiments |
Response sketch: { "items": [ Post ], "next_cursor": "...", "has_more": true }. The response can also say whether the order was ranked or recent so the app can show the right label.
Create post — POST /v1/posts. Use an Idempotency-Key so mobile retries do not create duplicate stories. The body carries text and media_ids[] already uploaded through separate upload URLs, because video bytes do not belong in JSON. Success is 201 with post_id and a processing state for media (pending / ready).
Follow graph. POST / DELETE follow return quickly. Graph updates become visible in the feed eventually, so say so if asked. Blocks remain a read-path safety filter regardless.
Status codes and errors. 401 means the caller is not logged in. 429 with Retry-After means the caller is being throttled, and create, follow and home reads are limited separately. A 404 or 403 for a blocked or private post should not reveal whether the blocked person exists. A 200 with a recency-ordered page is the right answer when the ranker is slow, not a 5xx.
How operators change behaviour. A small internal admin API lets the team change how the system behaves without deploying.
PUT    /v1/admin/feed/policy        # push/merge follower threshold, candidate cap
PUT    /v1/admin/feed/ranker        # on/off kill switch, deadline in ms
POST   /v1/admin/authors/{id}/tier  # force an author to push or merge
Cross-cutting behavior to name in the interview: rate-limit create and follow separately from home reads, document that cursors are opaque and what moving rank means, and keep reactions and comments off the feed p95 critical path unless they are in scope.
In the room (spoken): “Create returns after the post is safely saved. The fan-out catches up in the background with a different rule for very large authors. A home scroll loads a capped list of ids, loads the posts in one batch, filters blocks, ranks with a time limit, and returns a cursor. Post accepted and a follower seeing it are two different clocks. Operators can change the large-author rule and the ranker deadline through a small admin API.”
Deep dive: the questions an interviewer asks next
You have drawn the design and walked a publish and a scroll through it. This is the point where a good interviewer starts digging, and the questions usually come in a fairly predictable order, because each answer raises the next one. Read this section as that conversation. Each question is followed by an answer you can give, plus a hint of where the interviewer is likely to go next. When you can see the natural follow-up, say it before they ask.
“Walk me through one publish. What happens before you tell the author it worked?”
Think about who owns which promise. The post service owns saving the post safely and minting its id. Background workers own writing notes into personal lists where the policy says to push. The feed service that answers the author must not wait on millions of those inserts before saying success.
Here is the sequence. First, light checks on the new post: is the author allowed to post, and does the content pass basic policy? Second, the post metadata is saved, and any already uploaded media_ids are attached to it. Third, the post is saved in a durable way, meaning copied to more than one machine, and the author gets a 201 with the post_id. Fourth, a job such as { post_id, author_id, follower_tier_policy } is put on the fan-out queue. Fifth, workers expand the follower list in batches and write notes keyed by (viewer_id, post_id), so a worker that crashes and restarts cannot create duplicates.
Where it goes next: “Fine for a normal user. What if the author has 50 million followers?”
“What happens when a page with 50 million followers posts?”
Start with the version that fails. Under a rule that pushes to every follower, one post enqueues 50 million mailbox writes.
Post 201 ──► enqueue fan-out ──► 50M mailbox writes
                │
                └── queue age ↑  while API success looks fine
The create call still returns 201, so a dashboard that only watches post success stays green. But the queue is full of this one job, so other people’s posts wait behind it, and friends’ feeds look stale for minutes. The bill grows too, since every row is stored.
The better design classifies the author first. For long-tail authors it pushes as usual. For a very large author it stores the post once in an author-indexed recent list and the scroll merges it in for each viewer. Optionally it also pushes to the viewers who are active right now, so the people who are looking at the app see the post sooner.
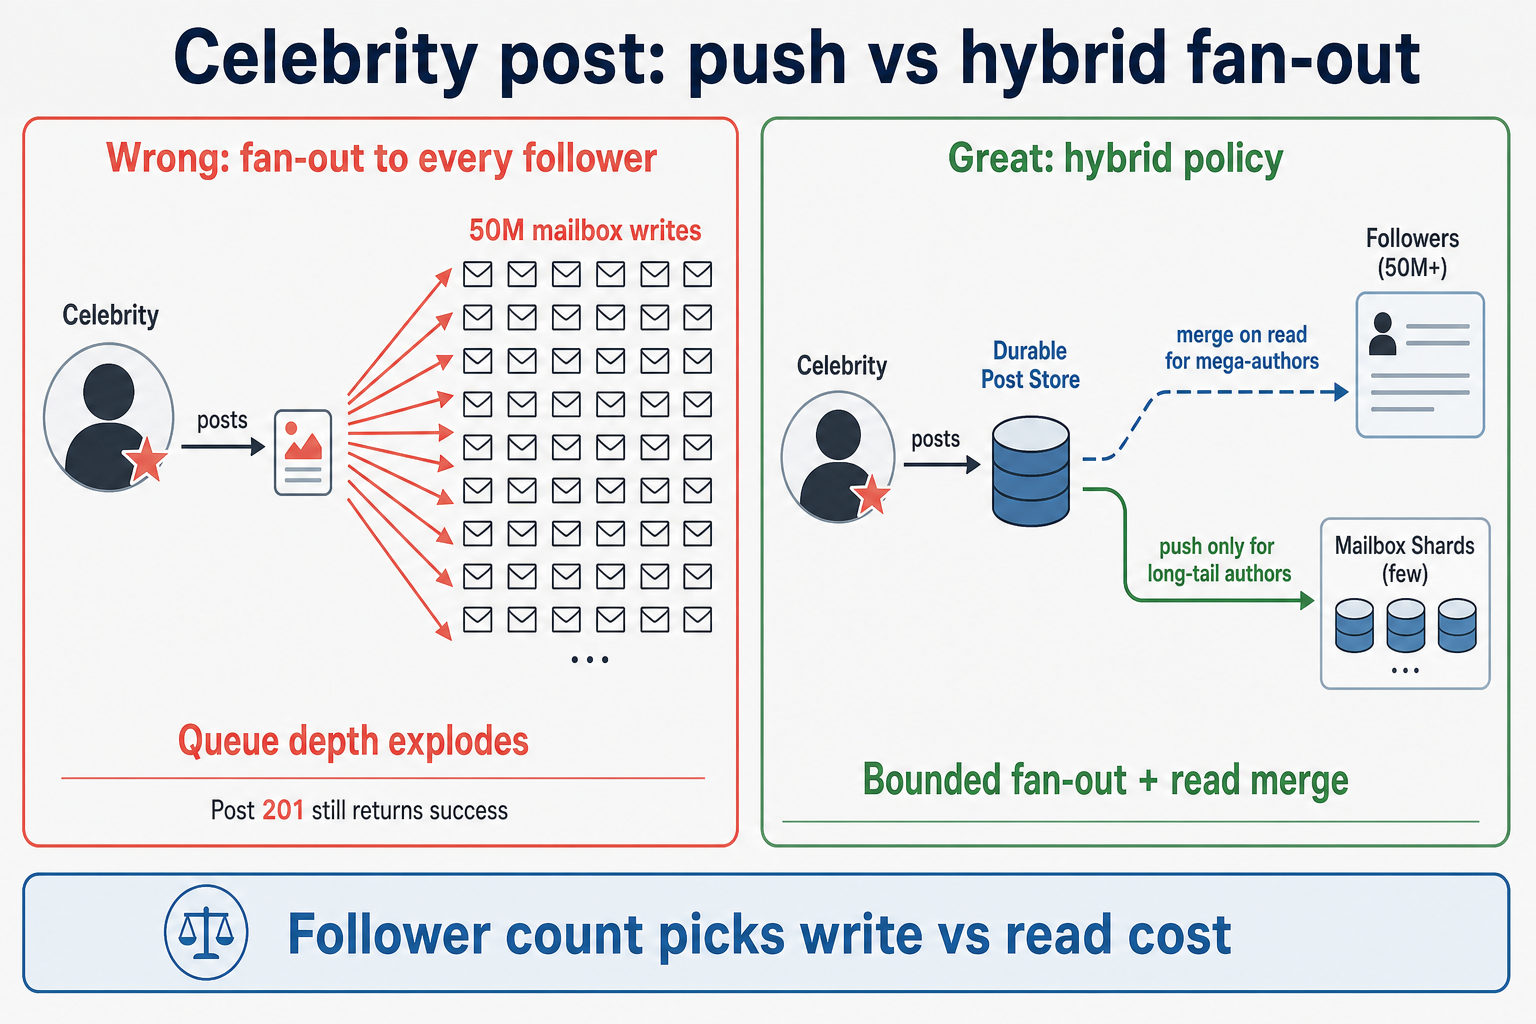
Figure: Follower count picks whether you pay on publish or on scroll. Pure push to everyone is a cost and lag incident waiting to happen.
Scale inside the box: Watch queue age, writes per shard, and the time to first visibility of sampled posts, not just the create success rate. Many people reading the same author’s recent list is its own hot spot, so that list is cached and copied to several machines.
Failure inside the box: If workers die in the middle of a fan-out, idempotent retries finish the job for the long tail. For a large author, active viewers still see the post through the merge, because it lives in the author’s list and does not depend on the queue at all.
Where it goes next: “Where exactly is the line between a normal and a big account?”
“How do you decide who counts as a big account?”
By follower count, with a threshold you choose from your capacity numbers, for example a few hundred thousand followers, and you say plainly that the exact number is a tuning knob. A useful way to say it is in three tiers: ordinary authors are pushed to everyone, middle accounts are pushed only to recently active followers, and the very large accounts are never pushed and are always merged on read.
Two details make the answer sound like experience. First, accounts move between tiers as they grow, so the tier is stored with the author and re-checked when new posts are published. When an author crosses the line, old posts already in mailboxes stay there, and new posts simply stop being pushed. Because the merge can return a post that is also in the mailbox, the feed service removes duplicates by post_id. Second, operators should be able to force a tier through the admin API during an incident.
Where it goes next: “Now walk me through one home page read.”
“Walk me through one page of the home feed.”
The scroll is a pipeline, and each step protects the time budget from something.
- Authenticate the viewer, then load the block and mute set from a cache that is kept strictly fresh for blocks.
- Read the head of the viewer’s mailbox, and merge in the recent lists of the big authors they follow. Stop at a cap of a few hundred candidates (the cap is what protects the p95 from someone who follows thousands of accounts).
- Batch-load the posts and author cards in one call, and drop anything deleted, hidden or from a blocked author.
- Ask the ranker for an order with a deadline of T milliseconds. On timeout, use newest-first or the last known order.
- Return a page of K posts and an opaque
next_cursor.
The sentence to say out loud is: “I never let ranking see an unbounded set, and I never let ranking own the edge’s thread pool without a timeout.”
Where it goes next: “What if the ranker gets slow?”
“What if the ranker’s p99 doubles after a deploy?”
The ranker is a separate service, and its slowness must not become the whole feed’s slowness. With a deadline in the call, the worst a slow ranker can do is turn the page into a newest-first page. A circuit breaker notices that the ranker keeps timing out and stops calling it for a short while, so the feed does not even pay the deadline. A kill switch lets the team turn off a heavy model quickly.
The deeper point is to keep two service targets apart. “The feed loads” is the promise to the person. “The order is perfect” is a goal. If a slow ranker can turn a goal miss into a promise miss, the design has coupled them wrongly. Watch the fallback rate, because a feed that quietly falls back all day looks green while the product gets worse.
Where it goes next: “And what do you do about page two, when the order has moved?”
“How does the next page work when scores change between requests?”
Take a concrete case. Page one shows posts scored 0.9 down to 0.7, and the last one shown is post 4410 at 0.71. While the person reads, a new post scores 0.95 and lands at the top. With an offset of 20, page two would start at what is now the 20th item, which is the post the person has already seen, so they would see a repeat.
With a cursor, the server returns something like (0.71, 4410) wrapped in an opaque string, and the next page asks for posts strictly after that position, so the repeat does not happen. The new 0.95 post does not appear on page two, and that is fine: it shows up when the person refreshes. The cursor can also hold a short-lived snapshot id so experiments stay consistent. The honest sentence is that scores can still shift, so a post may rarely be skipped, and the client should skip any post it has already shown.
Where it goes next: “What if someone blocks or unfollows between pages?”
“Someone blocks or unfollows someone. How does the feed update?”
The two cases are different. A block is a safety rule, so it is checked at read time against a block list kept fresh in a cache. Even if the blocked person’s ids are still sitting in the mailbox, the scroll drops them before building the page. An unfollow is a product preference, so it can be eventual: the feed service filters those authors on read, and a background job removes the old rows, or old entries expire on their own. Deleted posts work the same way, through a marker on the post that the scroll checks when it loads the body.
The reason not to clean the lists synchronously is the size: a deleted post from a popular author sits in many mailboxes, and a safety rule that waited for hundreds of millions of lists to be edited would not be a safety rule.
Where it goes next: “One viral post is in everyone’s scroll. What breaks?”
“One post goes viral and everyone loads it at once. What happens?”
Every scroll that includes that post asks the post service for the same post_id. When a cache entry for it expires, thousands of requests miss at once and all go to the post store, which is called a cache stampede. The feed still loads, but p99 climbs and the post service catches fire while the average cache hit ratio looks fine.
The fixes are small and specific. Collapse concurrent misses on one key into a single fetch (often called singleflight). Add a little random jitter to expiry times so entries do not all expire together. Serve a slightly stale copy while a fresh one is fetched in the background. And watch origin requests per key, not just cluster CPU.
The numbered happy path (put it together):
- Create a post, get a durable
post_id, return201. - Fan out (or skip it for a big author) so mailbox ids exist where the policy says they should.
- Home
GET: candidates, then load bodies, then filter, then rank or fall back, then cursor. - The next page uses the cursor, and block and delete filters are applied again.
Say it in the interview: “One policy decides who is pushed and who is merged on read. A scroll reads a capped list of ids, loads the posts in one batch, filters blocks, ranks under a deadline, and returns a cursor. Success on create and a fresh-feeling feed are two different targets, and I would measure both.”
If you remember one thing: The deep dive is a conversation. “Fan out to everyone” is the red flag, a size-based policy is the fix, and each answer is something you could have said before they asked.
Key challenges
The deep dive showed that each step is simple once the policy is clear. What makes the real system hard is everything around those steps, and a few hard parts show up again and again. Name them early in the interview, because each is a place the interviewer is likely to push.
| Challenge | What users see if it goes wrong | What to say in the interview |
|---|---|---|
| Celebrity copy-to-everyone | Friends’ feeds stuck while posting still “works” | Different rule for huge accounts; alert on queue age; merge big authors on scroll |
| Moving ranks | Duplicate posts or gaps while scrolling | Opaque continuation tokens; admit rare duplicates or skips |
| Follow graph changes | Blocked user still appears; unfollow feels stuck | Check blocks on every scroll; clean old rows later or let them expire |
| Scoring lag | Spinners or empty feed | Time limit plus newest-first fallback; stop calling a failing scorer for a while |
| Hot post cache stampede | One viral id melts the post store | One fetch per key when many miss at once; jitter expiry; watch origin hits per key |
If you remember one thing: Skew picks the fan-out policy, and moving rank picks cursor honesty.
Scaling the system
Those hard parts get worse as traffic grows, so the next question is what happens when the number of people multiplies. You do not have to wait for the interviewer to ask. Right after you finish the design, say the scaling story yourself, then be ready for the follow-ups.
What you can say upfront: “Reads are the load, so I would scale them first. The mailboxes are split across many machines by viewer id, so one person’s list lives on one shard and the load spreads evenly across people. Post bodies are split by id and sit behind a cache and a CDN, with jittered expiry and merged misses so one viral post cannot stampede the store. The write side scales by adding fan-out workers, with a size rule that keeps very large accounts out of the push path. Someone who follows thousands of accounts is capped on how many sources the merge reads. And across regions I prefer local reads with fan-out that catches up later, instead of promising one globally consistent list.”
That one paragraph answers most of what follows. Here are the follow-ups, in the order they usually come.
Interviewer: “Traffic doubles next quarter. What do you change?”
You: “The feed service machines first, because they hold no important state: the lists are in the mailbox store and the bodies are in the post service, so I add more of them behind the load balancer. Then I look at the stores: shard count, memory and the busiest keys. The fan-out workers scale by adding more consumers on the queue, as long as the writes are idempotent. I would size the next step from the capacity numbers and confirm it with a load test.”
Interviewer: “How do you split the mailboxes?”
You: “By
viewer_id, so each person’s list is on one shard and a scroll is one lookup. With hundreds of millions of viewers the load spreads well on its own. I avoid joins on the hot path: I load bodies by id in a batch. The cost is that a publish for an ordinary author becomes many small writes to many shards, which is why that work is done in the background.”
Interviewer: “A famous account posts. Doesn’t reading that author’s recent list become the hot spot?”
You: “Yes, and it is the other side of the same decision. I moved the cost from millions of writes to millions of reads of one small list. That list is tiny and changes slowly, so I cache it aggressively, copy it to several machines, and let each feed machine hold it in memory for a few seconds. The cost is that a very new post from the big account can show up a few seconds late, which is acceptable.”
Interviewer: “Someone follows 5,000 accounts. Does the scroll still work?”
You: “It works because the scroll is capped. The mailbox gives a precomputed head, and I only merge the handful of big accounts they follow, with a cap on how many sources I read. If someone follows an unusual number of big accounts I cut the merge to the most recently active ones. I would rather return a slightly less complete feed in time than read everything and miss the 300 ms.”
Interviewer: “What about more than one region?”
You: “Reads stay local to the region. Posts are copied between regions, and each region runs its own fan-out for its local followers, so a friend in another continent may see a post a bit later. I say plainly that I am not promising one atomic global view. Blocks are the exception, so the block list is replicated quickly and checked on every read.”
If you remember one thing: Scale reads with sharded mailboxes + a CDN, and scale writes with background fan-out + a size rule, not with bigger SQL joins.
Failure handling
Scaling answers “what if there is more traffic”. This section answers “what if something breaks”. Again, say it first. Failures here come from the ranker, the queue, the stores and the caches, and what impresses an interviewer is that the answer was decided before the failure happened.
What you can say upfront: “Every failure has a decision made in advance, and the common rule is to degrade the quality of the feed, not to take the feed away. If the ranker is slow or down, the scroll falls back to newest-first after a deadline and a circuit breaker stops calling it. If the fan-out queue backs up, posts from ordinary authors show up late, and the big-author merge and active-viewer pushes cover the gap while we alert on queue age. If a store is degraded, I serve slightly stale but safe pages where the product allows it. Safety rules such as blocks are never degraded.”
The follow-ups are about the details of those decisions.
Interviewer: “The ranker times out. What does the person see?”
You: “A feed, in newest-first order. The scroll has a deadline on the ranker call, and when it passes the feed returns the recency-ordered candidates or the last good order it remembers. After repeated timeouts, a circuit breaker stops calling the ranker for a short time so the deadline is not paid on every scroll. The person might notice a less relevant order but never a spinner. I would alert on the fallback rate, because a quiet fallback all day is a problem even if no error is shown.”
Interviewer: “The fan-out queue is hours behind. What breaks?”
You: “Create still returns
201, so the usual dashboard is green, but friends see yesterday’s feed. I alert on queue age and per-shard backlog, not only post success. While it drains, the merge on read covers the large accounts, I give recent posts a priority lane so new publishes are not stuck behind a backlog, and I cap how much each worker does per tick. Idempotent writes mean I can replay jobs safely.”
Interviewer: “One mailbox shard is down. Do those people lose their feed?”
You: “They should not. For those viewers I fall back to pulling recent posts from the accounts they follow, with a small cap, or I serve a recently cached page. It is slower and less complete, but it is a feed. The replicas of that shard take over, and the fan-out workers catch up with replays.”
Interviewer: “The post store is degraded and some cards would be blank. What now?”
You: “A circuit breaker stops the calls that keep failing, and I serve slightly stale but safe slices, such as a cached copy of the post, where the product allows it. I never show a blank card. And I would not serve stale copies for anything that carries a safety rule, like a deleted post or a blocked author.”
Interviewer: “How do you explain two people disagreeing about whether a viral post showed up?”
You: “Fan-out across regions is not one transaction. Regional shards and at-least-once workers mean visibility is eventual, so two people can see it at different times. I make writes idempotent, watch lag across regions, and never promise instant worldwide delivery.”
| Scenario | What the user sees | What to build |
|---|---|---|
| Ranker slow or down | Spinners or empty home | Hard timeout; recency fallback; feature-flag heavy models |
| Fan-out backlog | Post succeeded; friends see stale home | Alert on queue age; lean on merge-on-read; priority lanes |
| Cache stampede on hot post | p99 spike on one ID | Singleflight; stale-while-revalidate; jittered TTL |
| DB / post store degraded | Errors or blank cards | Circuit break; serve stale-but-safe slices where product allows |
| Mailbox shard down | Empty home for some people | Fall back to a capped pull; replicas; replay fan-out |
If you remember one thing: Degrade ranking (recency, stale slice), and do not block the edge forever behind a slow ranker.
Observability (what you measure)
Once the system is live, you need a way to tell whether it is healthy, and that takes more than one number. The danger in a feed is that the part you are confident about, accepting posts, stays green while the part people feel, seeing them, quietly gets worse.
| Signal | Why it matters |
|---|---|
| Post create success vs fan-out queue age (how old the oldest waiting copy job is) | Explains “posted but friends don’t see it” |
| Time-to-first-visibility (sampled: how long until a follower’s list shows the post) | Product freshness target |
| Ranker p99 (slowest 1 in 100 scoring calls) + timeout / fallback rate | Separates score health from “the feed still loads” |
| Candidates scored per request | Catches an unbounded merge that blows the time budget |
Origin fetches per hot post_id (requests that miss cache and hit the post store) | Detects a stampede on one viral post |
| Empty feed / 5xx rate | User-visible outages |
Green create rates alone will lie while timelines feel stale.
Security and abuse
A feed decides what a person is allowed to see, so this section covers how to keep that honest when people try to cheat or when privacy rules collide with lag. Every home scroll and every create call should prove who is calling before any work starts. Who may see a post—friends only, public, or blocked—must be checked on read, not only at the moment a note was copied into a list, because lists can lag. Cap how fast someone can create posts, follow accounts, or react, so spam and follow-bots cannot flood the product. Treat ranking and analytics logs carefully: do not dump private post bodies into unrestricted analytics without access control. Pipelines that catch fake engagement and coordinated amplification belong beside the feed; they should not rewrite every personal list on the spot.
Cost awareness
Every choice so far also has a price, and interviewers like to hear that you noticed. Every note pushed into a personal list costs storage and write capacity until it expires. Pushing to every follower of a very large account is a cloud bill incident, not a clever scale story. Scoring huge candidate sets burns CPU on every scroll. Nearby file servers and object storage dominate media cost, so keep photo and video bytes off the personal-list path. Caching reduces load on the post store but adds complexity, so buy cache where keys are hot and stampedes are measurable. Choose explicitly whether you spend money on storage for work done in advance or CPU at scroll time for merging.
Green Dashboard. Angry Users. The Production Mindset System Design Interviews Expect.
Everything so far describes how the feed should work on a good day. This section is about what happens on a bad day, told as short stories from the people who carry the pager (the on-call engineers). Textbooks teach boxes and arrows. On-call teaches this: post create can look healthy while the home feed feels stuck in yesterday.
Three nightmares that look fine in the middle:
| What the dashboard shows | What is actually happening |
|---|---|
| Post create 201 rate is green. | Fan-out queue age is climbing; friends refresh and see old stories. |
| Ranker error rate is low. | Ranker p99 ate the gateway thread pool; feeds hang without many 5xx. |
| Cluster CPU looks calm. | One viral post_id is stampeding the origin after a synchronized TTL expiry. |
Scene 1: Fan-out backlog while posts “succeed”
The moment: A live event is happening, or a famous account posts. Publishing still returns success for everyone who taps Share. Friends refresh and still see yesterday at the top of their feed, and support tickets start to say “my friend’s post is missing.”
The trap: Copying post ids into follower lists runs in the background at a finite speed, and the workers are working through a long queue. Dashboards that only chart “post accepted” hide time to visible—how long until a follower actually sees the story. The metric that lied was the create success rate.
What to build: Alert on queue age (how old the oldest waiting job is) and per-shard backlog. Cap how much each worker copies per tick, and lean on merge on read for large authors while the queue drains. Give brand-new posts a priority lane so they are not stuck behind the drain.
Scene 2: A ranker deploy hangs the feed
The moment: After a new scoring model ships, home feeds spin on open, and even routes that have nothing to do with ordering posts feel slow.
The trap: The scoring service sat on the busiest path with no time limit. Waiting calls filled the edge’s free worker threads, so everything behind that edge queued up—even pages that never call the scorer.
What to build: A hard scoring timeout, a circuit breaker that stops calling a failing scorer for a short while, a newest-first fallback, and a kill switch for heavy models. Keep separate targets for “the feed loads” and “the order is perfect.”
Scene 3: “I see it, you don’t”
The moment: Two coworkers open the same app after lunch and disagree about whether a viral post appeared in their feeds.
The trap: Spreading one post to every region is not one atomic transaction. Lists live on regional machines, and background workers may deliver a job more than once, so visibility catches up at different times—and both coworkers can be telling the truth.
What to build: List writes that are safe to retry without duplicates, plus dashboards on how far regions lag each other. Do not promise instant worldwide delivery.
Scene 4: Cache stampede on a hot post ID
The moment: One post goes viral. The feed still loads, but the slowest scrolls get much slower and the post service catches fire, while the average “cache hit” percentage still looks fine.
The trap: Every scroll loads the same post id, and many cache entries expire at the same second, so a herd of requests miss at once and all hit the post store together.
What to build: Collapse concurrent misses on one key into a single fetch (often called singleflight), add a little random jitter to expiry times, serve a slightly stale copy while a fresh one is fetched, and watch origin requests for one key, not only cluster CPU.
In the interview: Pick one scene. Tell what people felt, which metric lied, and what you would ship next. You do not need all four. You need to sound like someone who knows that green does not mean done.
Bottlenecks and tradeoffs
Those stories all trace back to a small number of choices where you cannot have both things you want. Interviewers listen for whether you can name the tension, say what breaks, and pick a side on purpose. Here are the three that matter most for a feed.
Precompute vs read-time merge
The tension — Writing every follower’s mailbox makes the scroll fast, but large accounts make the write amplification impossible.
What breaks — Fan-out queue depth explodes; one post becomes tens of millions of rows.
What teams do — Hybrid: push for normal accounts, merge on read for the head; alert on queue age.
Say in the interview — Name who you push to and who you merge at read, not just “we fan out.”
Fresh ranking vs stable pagination
The tension — People want a relevant order, but a cursor wants a stable continuation.
What breaks — Duplicates or skips when scores shift between page loads.
What teams do — Opaque cursors, session snapshots, client-side duplicate skipping; admit best-effort.
Say in the interview — Offset/limit at scale is a trap; cursor + honesty beats fake consistency.
Cost vs freshness
The tension — More precomputed mailboxes smooth reads, but they cost storage and fan-out CPU.
What breaks — Thin mailboxes push merge work into the p99 read when someone follows thousands of accounts.
What teams do — Cap candidates before ranking; trim mailboxes by age; put cold tails on cheaper storage.
Say in the interview — Pick what you buy with money: storage or read CPU.
If you remember one thing: Every feed tradeoff is where you pay: at publish, at scroll, or in on-call when queues lag.
Interview tips
You now have a full design and the tradeoffs behind it, so the last thing to practice is defending it when the interviewer pushes back. These five are the pushes that come up most after you finish the design.
Fan-out on write only — celebrities melt the queue
In the room
You might say: “When someone posts, we copy the post id into every follower’s list.”
Interview Push: “A page with 50 million followers publishes. What happens to your queue and storage?”
Land here: One click then means on the order of fifty million list writes if you copy to everyone. Use a hybrid policy: push for ordinary authors where copying is cheap; for mega-followed authors, merge on read, push only to people who are online, or store recent posts by author and combine at scroll time. Name queue depth and blast radius, not only a queue product. If create still returns success while the oldest job in the queue grows older, friends’ feeds look stale, and that is an operations story you should volunteer.
Where post bodies live — pointers on the timeline
In the room
You might say: “The feed service stores everything in one database.”
Interview Push: “What travels on every scroll, full post JSON or pointers?”
Land here: Keep two stores. Each viewer’s mailbox holds only ordered post ids (or score and id), split across machines by user id. A separate post service, plus file storage and a nearby CDN for media, owns the bodies. The feed path loads those bodies by id in one batch and caps how many it considers. Shipping full bodies in every follower row multiplies storage and makes edits and deletes painful.
Ranking as one box — timeouts beat perfect scores
In the room
You might say: “We call the ML service and sort.”
Interview Push: “The ranker’s p99 doubles. Does the whole app hang?”
Land here: First pick a capped list of candidate ids, then score only that list. Put a hard timeout on scoring and fall back to newest-first or the last good page. Add a circuit breaker so the edge does not sit forever on one dependency. A perfect order that empties the feed is a product failure, not a win.
Pagination with moving order — cursors over offsets
In the room
You might say: “We use offset and limit; page 2 is easy.”
Interview Push: “Scores change between requests. Do people see duplicates or gaps?”
Land here: Hand the client an opaque cursor—a bookmark it cannot read—or a
(score, post_id)continuation, so page two continues after what it already saw. Admit best-effort stability, with rare duplicates or skips, instead of faking a perfectly stable order. Skip-N offsets at feed scale are a trap because the list underneath keeps moving.
Blocks and unfollows — safety now, purge later
In the room
You might say: “When someone unfollows, we delete all their feed rows right away.”
Interview Push: “A post is deleted or an author is blocked. Can you edit every list that holds it before the next scroll?”
Land here: You cannot rewrite every list on the spot, because the same post can sit in hundreds of thousands of personal lists. Unfollow can catch up later. Filter blocks and deleted posts on every scroll for safety even if a stale id still sits in a list, and use expiry, a lazy filter, or background cleanup for the softer changes. Brief unfollow staleness is usually okay; block paths are not.
Red flags to avoid without correcting yourself: “Fan out to everyone,” “offset pagination,” “rank with no timeout,” “one DB holds full posts in every feed,” “edit every mailbox synchronously on delete.”
After each interview push, close with one real part of the design you would build: the follower-count threshold, the idempotent (viewer_id, post_id) write, the ranker timeout, or the opaque cursor. Do not close with “we’ll scale it later.”
What should stick
After working through the requirements, the decisions and the depth sections, you should be able to explain:
- Read:write skew — Almost everyone scrolls and few post, so do the heavy work once at publish, and expect large accounts to break any rule that treats every author the same.
- Hybrid fan-out — Push where it is cheap; merge or pull for the head; policy by follower count.
- IDs vs bodies — Mailboxes hold order; posts and media live elsewhere and load in a batch.
- The ranker is best-effort — Bounded candidates, a timeout, a recency fallback, and never block the edge.
- Cursors over offsets — Moving rank means honest dup/skip, not fake strong consistency; blocks are checked at read.
Tell it in the room: “Home feed: the post is saved durably first, then idempotent background fan-out writes ids into mailboxes where the policy says push. Very large authors are merged on read. A scroll loads capped candidate ids, loads bodies in a batch, filters blocks, ranks with a timeout, and returns a cursor. When fan-out lags, people still scroll slightly stale mailboxes; when the ranker lags, we fall back to recency.”
Quick check before a mock: (1) What does one post from a 50M-follower account cost under pure push? (2) What is in a mailbox row? (3) What happens when the ranker is late? → (1) about 50 million writes (2) a post id, an author id and an ordering value, not the body (3) return newest-first or the last good order.
Practice next: Open Design a Facebook Feed on Practice System Design and run a timed attempt using clarifying questions, one publish story and one scroll story.
Key Takeaways
- Do the heavy work once at publish time, because scrolling is far more common than posting; each viewer’s list stores only ordered post ids, while bodies and media live in the post store.
- Treat very large accounts differently: push for ordinary authors, keep a large author’s recent posts by author and merge them in on read, and say the follower-count threshold out loud.
- Confirm a post as soon as it is durable; fan-out runs in the background with idempotent writes keyed by
(viewer_id, post_id). - Cap the work of every scroll: a few hundred candidate ids, one batch load of bodies, block and delete filters, then ranking under a deadline.
- Give the ranker a hard timeout, a circuit breaker and a newest-first fallback, so a slow model produces a worse feed, never an empty one.
- Use opaque cursors instead of offsets, and admit that rare duplicates or skips are the honest result of a moving order.
- Watch fan-out queue age, time to first visibility, ranker fallback rate and origin requests per hot post, not just post create success.
Related Topics
- WhatsApp System Design - Messaging contrast: per-thread order vs feed fan-out and ranking
- Notification Service System Design - Async fan-out after the durable write
- Rate Limiter System Design - Protecting create and follow from abuse
- Distributed Cache System Design - Hot post keys, stampede, and TTL jitter
- Facebook Post Search System Design - Search indexing beside the hot home path
Quick revision notes
The problem in your own words. A home feed shows each person a fast, sensible page of posts from the accounts they follow. The hard part is that scrolls are far more common than posts, and a few accounts have so many followers that copying each post to every follower is too expensive.
The design in one breath. A post is saved first and the author is told it worked. Background workers write the post’s id into follower mailboxes, except for very large authors, whose recent posts are kept by author and merged in when someone scrolls. A scroll reads a capped set of ids, loads the bodies in one batch, drops blocked or deleted posts, asks the ranker for an order under a deadline, and returns a page and an opaque cursor.
The choices you must be able to defend. Push for ordinary authors and merge for big ones, with a threshold you can name. Ids in the mailbox and bodies in the post store. A ranker deadline with a newest-first fallback. Cursors instead of offsets. Block and delete checks at read time, with cleanup in the background.
The numbers worth remembering. One post from a 50-million-follower account is about 50 million writes under pure push. Roughly 60 billion list writes a day if even ordinary authors average 200 followers (an estimate). A scroll has about 300 ms, and only a few hundred candidates should be considered.
The mistakes that cost points. Fanning out to everyone, offset pagination, ranking with no timeout, storing full posts in every follower’s list, and cleaning every mailbox synchronously when something is deleted.
Frequently asked follow-ups
- Copy notes into follower lists at publish time, look them up at scroll time, or mix both?
- How do you handle an account with 50 million followers?
- What happens when the scoring step is slow?
- How do you fetch the next page when scores change between scrolls?
- What do you alert on when posts succeed but feeds still feel stale?
Deep-dive questions and strong answer outlines
Walk through a normal user publishing one post.
Save the post’s metadata (and upload photos or video on a separate path). Tell the author it worked as soon as that record is safely saved—do not wait until every follower’s personal list is updated. Put a background job on a queue to copy a small note (keyed by viewer and post so a retry cannot duplicate it) into ordinary followers’ lists. For mega-followed authors, skip that full copy and merge their recent posts when someone scrolls. Search indexing, notifications, and link previews start only after the post row exists.
How do celebrity accounts change the write path?
Do not write tens of millions of personal-list rows for one post. Mark the author for a hybrid rule: keep recent posts indexed by author, optionally copy only to people who are online right now, and blend those recent posts into each home scroll. Name the cost drivers—how deep the work queue grows, how much storage you burn, and how far one post’s blast spreads—not only a queue product name.
Walk through reading one page of the home feed.
Load a capped set of candidate post ids from the viewer’s personal list, plus any merge of mega-followed authors. Fetch those post bodies and author cards in one batch. Drop blocked or unsafe posts. Score under a hard time limit, or fall back to newest-first if scoring is late. Return the page plus an opaque continuation string for the next scroll, and keep the candidate cap small so most scrolls finish in the time budget.
What if the ranker p99 doubles after a deploy?
Put a hard time limit on the scoring call. If it keeps failing, stop calling it for a short while (a circuit breaker). Return a newest-first page or the last good order. Keep “the feed loads” as a harder promise than “the order is perfect,” and do not let the edge sit forever waiting on one dependency.
Someone unfollows or blocks—how does the feed update?
Blocks are a safety rule, so check them on every scroll against a fresh enough block list. Unfollow can catch up later: filter at read, let old list rows expire, or delete them in the background. Do not try to rewrite every personal list on the spot when the graph has a huge number of edges.
AI feedback on your design
After a practice session, InterviewCrafted summarizes strengths, gaps, and interviewer-style expectations—similar to a written debrief. See a static example report, then practice this problem to get feedback on your own answer.
FAQs
Q: How deep into ML ranking do I need to go in a system design interview?
A: Usually you describe the interface—which post ids and signals go in, how many milliseconds you will wait, and what you show if that wait expires—not how models are trained. Name how fresh the feed should feel and a newest-first fallback. If they push on models, keep one sentence on signals and return to how posts reach followers and how the next page works.
Q: Is fan-out on write enough by itself?
A: Copying a note into every follower’s list at publish time works for modest follower counts and fails for celebrities. Looking up every followed account at scroll time works for mega-authors and can burn CPU when someone follows thousands of accounts. Strong answers name a hybrid policy with an explicit follower-count threshold or author tier.
Q: Do feeds need strong consistency across every follower instantly?
A: Usually no. A few seconds of lag after someone posts is acceptable for home feed. Blocks and hard safety are stricter—filter them on every scroll even if personal lists are still catching up. Say that bar out loud so you are not promising that every follower worldwide sees the post in one atomic step.
Q: How is a news feed different from a chat product like WhatsApp?
A: Feeds optimize getting many followers a page of posts quickly, then ordering that page and keeping scroll latency low. Chat optimizes per-thread order, delivery receipts, and often strong privacy. Feeds tolerate brief staleness; chat users notice hundreds of milliseconds. See WhatsApp System Design for the messaging contrast.
Q: Why not offset/limit pagination for home feed?
A: The ranked order moves between requests, so “skip the first 20” can repeat a post or skip one. An opaque continuation string (or a score-plus-id bookmark) plus the client skipping anything it already showed is the honest contract at this scale.
Q: What should I alert on in production?
A: How old the oldest fan-out job is and how deep each shard’s backlog runs, how slow the scorer’s worst requests are and how often you fall back, how long a sampled post takes to appear in a follower’s list, how many origin fetches one hot post id causes, and how often the feed returns empty or errors—not only whether create post returned success.
Practice interactively
Open the practice session to use the canvas and stages, then review AI feedback.